A data loss prevention risk assessment finds where sensitive data lives, who and what can reach it, and which exposures to fix first. See how Strac automates it. Benefit-led (158 characters):
· A data loss prevention risk assessmentidentifies sensitive data across your environment, maps who and what can accessit, scores each exposure, and produces a ranked risk register that drivesremediation.
· The scope changed in 2026: the riskiest accesspaths now include browser tabs pointed at chat assistants, OAuth grants tounvetted apps, and AI agents reading data through MCP servers, none of whichappear in a traditional data inventory.
· An annual, interview-driven assessment describesa snapshot that is out of date within a week. The gap between assessments iswhere the exposure sits.
· Strac turns the assessment into a continuousloop: discovery and classification across SaaS, cloud, endpoint, browser, GenAIand MCP, DSPM posture scoring, and automated remediation that closes findingsthe moment they appear.
· Thisis the assessment slice of AI data governance.Start from that pillar if you are building the wider program.
What Is a Data Loss Prevention Risk Assessment?
A data loss preventionrisk assessment is a structured review of where sensitive data sits, how it moves, who can reach it, and what would happen if it leaked. The output is a prioritized list of exposures, each with an owner and a fix.
A good assessment answers four questions. Where is the data? Who and what can reach it? How likely is exposure, and how bad would it be? What do you fix first? A report that answers the first question and skips the last three is an inventory, not an assessment.
Why the Annual Assessment Broke
The classic DLP risk assessment was built for a stable environment: a few file servers, an email gateway, managed laptops. You interviewed data owners, walked the systems, scored the risks, and filed a report that held up for a year.
That model fails for three reasons.
The inventory moves daily. A single shared Google Drive link, a new Slack channel, or an export dropped into a ticket changes the exposure picture before the report is signed.
The access path is no longer only human.Shadow AI tools, OAuth-connected apps, and agents calling tools over MCP all hold standing access to sensitive data, and interviews with data owners never surface them.
The fastest leak leaves no file behind. A paste into a chat assistant exfiltrates a customer record in one second, through a channel legacy DLP never inspected.
An annual assessment tells you what your risk was. A continuous one tells you what it is.
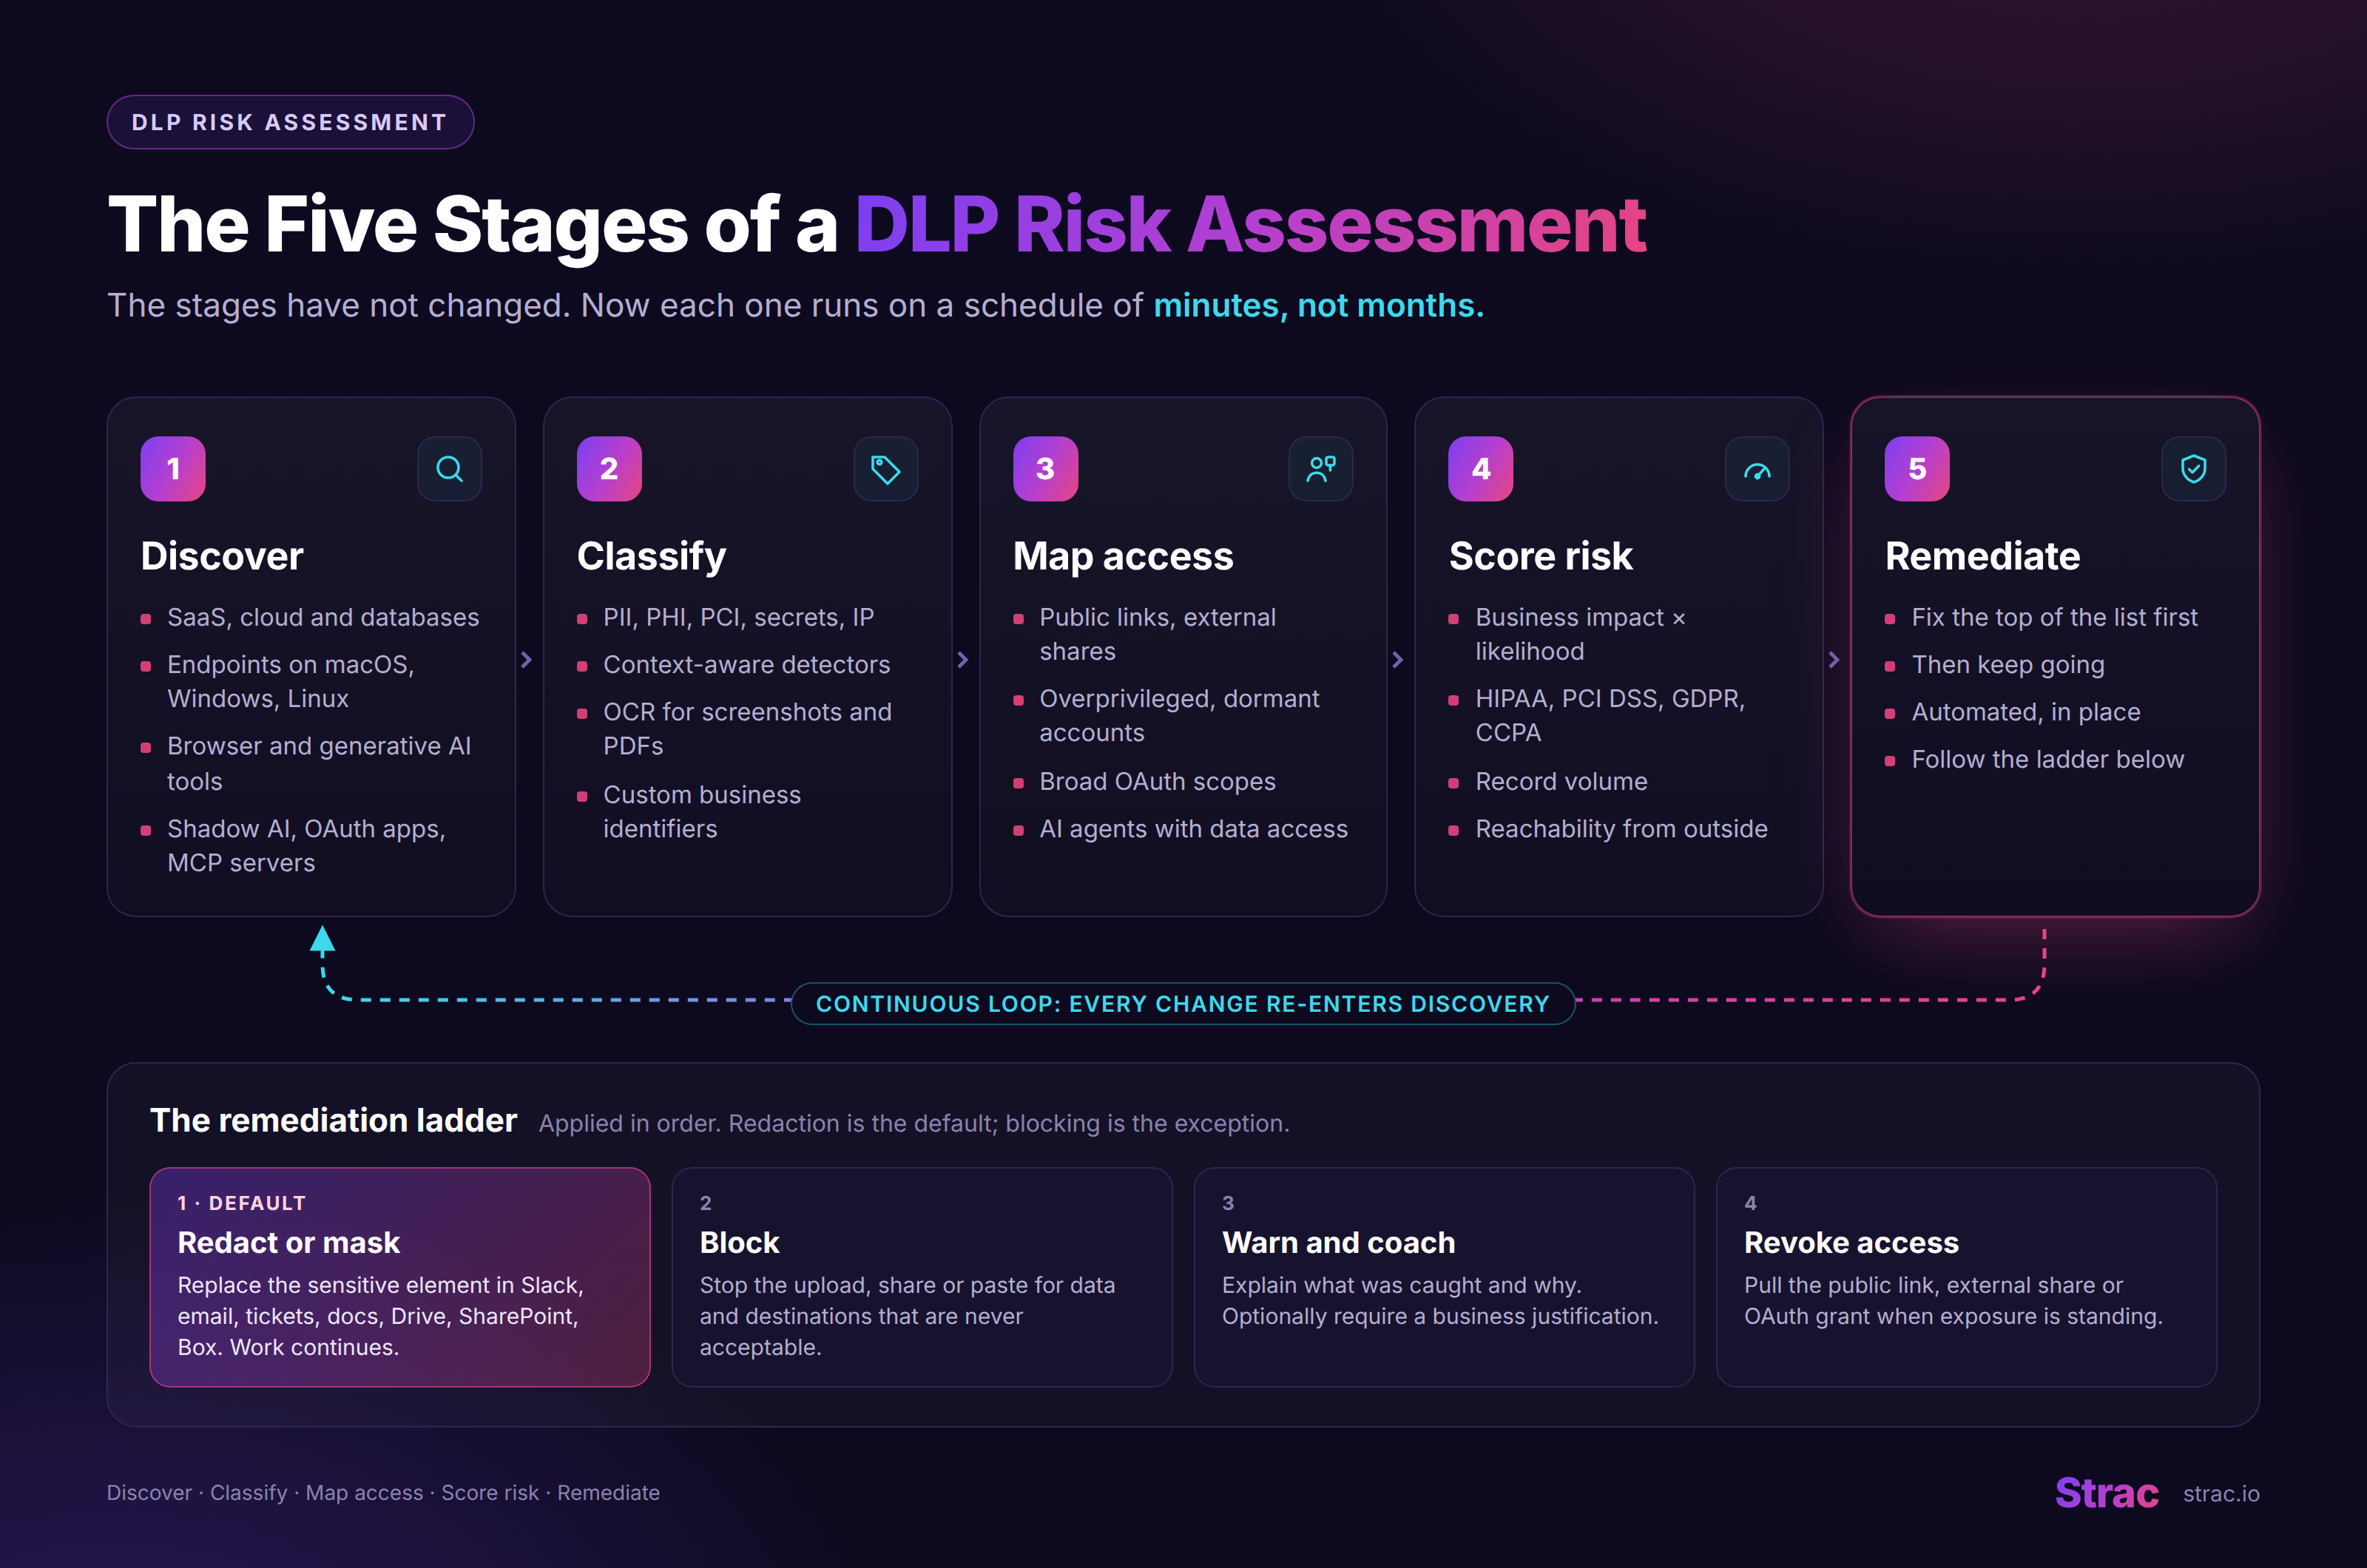
✨ The Five Stages of a DLP Risk Assessment
The stages have not changed. What changed is that each one now has to run on a schedule measured in minutes, not months.
1. Discover. Find sensitive data wherever it lives: SaaS apps like Slack, Google Workspace, Microsoft 365, Salesforce, Zendesk and Jira; cloud storage and databases; managed endpoints on macOS, Windows and Linux; and the browser, where data flows into generative AI tools. Discovery in 2026 also means discovering the tools themselves: unsanctioned AI apps, OAuth grants, and the MCP servers your agents connect to. See how to detect shadow AI for that half of the problem.
2. Classify. Label each finding by data type and sensitivity. Pattern matching alone generates alert fatigue, so classification needs detectors that understand context, OCR for screenshots and scanned PDFs, and custom detectors for identifiers unique to your business. The catalog of sensitive data elements is a useful baseline.
3. Map access. For every sensitive asset, answer who and what can reach it. Look for public links, external sharing, overprivileged groups, dormant accounts, and third-party apps holding broad OAuth scopes. Include non-human access: an agent with a database connection is an access path, whether or not a person is behind the request.
4. Score risk. Rank each exposure by business impact and likelihood. A spreadsheet of card numbers shared publicly outranks an internal doc with one employee address. Factor in regulatory weight under HIPAA, PCI DSS, GDPR and CCPA, the volume of records, and how reachable the asset is from outside the company.
5. Remediate. Fix the top of the list first, then keep going. The remediation ladder, in order:
Redact or mask. Replace the sensitive element in place in Slack, email, tickets, docs, Google Drive, SharePoint and Box, so work continues and the data does not travel.
Block. Stop the upload, share or paste for the narrow set of data classes and destinations that are never acceptable.
Warn and coach. Tell the person what was caught and why, and optionally require a business justification before they proceed.
Revoke access. Pull the public link, the external share, or the OAuth grant when the exposure is standing rather than momentary.
What Belongs in the Risk Register
The risk register is the deliverable. Each entry should hold enough to act on without a follow-up meeting:
The asset and where it lives
The data classes it contains and the record volume
Who and what can access it, including apps and agents
The impact and likelihood score, and the resulting priority
The frameworks the finding touches
The chosen remediation and its owner
The status, with a timestamp for when it closed
A register that updates itself is an operating tool; a register that updates once a year is a historical document.
From Finding to Fix in One Motion
Watch Strac detect a card number in a Gmail thread, classify it, and redact it inline before the message reaches its recipient.
A finding that closes itself is worth more than a finding that waits for the next quarterly review.
This is where most assessments stall. The report names the risk, a ticket gets filed, and the exposure stays open until someone has time. When discovery, scoring and remediation run on the same platform, the time between "found" and "fixed" collapses from weeks to seconds.
🎥 Strac: Continuous Risk Assessment on the Data Layer
Strac runs every stage of the assessment on one platform, continuously.
Discovery and classification. Strac scans SaaS, cloud and endpoints in real time and historically, with built-in detectors for PII, PHI, PCI data, secrets and source code, OCR for images and documents, and custom detectors you can create in minutes. Sensitive data discovery and classification covers the long tail of apps, including Slack DLP, Google Drive DLP, Salesforce DLP, Zendesk DLP and Jira DLP.
Access mapping and scoring.Data security posture management (DSPM) surfaces overexposed files, public links and excessive access, then remediates posture risks automatically by revoking access, applying labels or redacting fields. Data lineage follows corporate files from their origin across endpoints, even after they are modified.
Every surface where data moves.SaaS DLP covers collaboration and support tools. Endpoint DLP enforces policy on macOS, Windows and Linux. Browser DLP inspects pastes and uploads, which is where AI DLP stops sensitive data from reaching ChatGPT, Claude and Gemini. MCP DLP redacts sensitive data from tool responses before it reaches the model, so an agent with broad access still cannot exfiltrate raw records.
Remediation and evidence. Policies range from a nudge to a justification prompt to a hard block, with redaction as the default. Every detection and fix is logged, which turns the risk register into audit evidence for SOC 2, ISO 27001, HIPAA, PCI DSS and GDPR. For the proof side, see data loss prevention compliance.
The difference is structural. A consulting-led assessment ends with a report. A Strac assessment ends with the exposures already closed.
Your DLP Risk Assessment Checklist
☐ Every surface in scope: SaaS, cloud, endpoint, browser, generative AI, MCP
☐ Unsanctioned AI tools and OAuth grants discovered on a schedule
☐ Detectors tuned for your own identifiers and tested on real files and images
☐ Access mapped for people, apps and agents alike
☐ Every finding scored by impact and likelihood, with a named owner
☐ Remediation defaults to redaction, with blocking reserved for the narrow cases
☐ Risk register updates continuously and exports with timestamps
Identity, network and policy controls all fail eventually, and an assessment that only describes them tells you little about the data. The data layer is the backstop: find sensitive data everywhere, score it continuously, and redact it on every action, so a compromise never becomes a breach. Strac runs that loop across SaaS, cloud, endpoint, browser, GenAI and MCP. Book a demo to see your risk register build and close itself.
🌶️ Spicy FAQs on DLP Risk Assessments
Is a DLP risk assessment the same as a DSPM scan?
No. A DSPM scan finds and scores posture risk in data at rest. A DLP risk assessment also covers data in motion: pastes, uploads, messages and agent tool calls. Strac runs both on one platform, so the register reflects the whole picture.
Why doesn't our last penetration test or audit cover this?
Because those test systems and controls, not the data itself. A pen test shows whether an attacker can get in; a DLP risk assessment shows what they would find and where it would go. Both are needed, and they answer different questions.
Does acting on the findings mean blocking AI tools?
No. Blocking pushes usage to personal devices, where you lose visibility entirely. Redaction lets people keep using generative AI while the sensitive element never leaves, which lowers the risk score without lowering productivity.
Can a risk assessment find every piece of sensitive data?
Not with certainty. Detection has false negatives, and new tools appear faster than any inventory. That is why remediation belongs at the data layer: when something slips through discovery, redaction on every action keeps a missed file from becoming a breach.
How often should a DLP risk assessment run?
Continuously. Frameworks like ISO 27001 and SOC 2 require periodic risk assessment, but the environment changes daily. Run discovery and scoring all the time, and formally review the register quarterly. See AI data governance for how this fits the wider program.
Discover & Protect Data on SaaS, AI, MCP, Endpoints & Cloud
Strac provides end-to-end data loss prevention for all SaaS and Cloud apps. Integrate in under 10 minutes and experience the benefits of live DLP scanning, live redaction, and a fortified SaaS environment.