How to Protect Customer Information in 2026: DLP, Data Lineage & AI Governance
Customer data now leaks through AI prompts, agent tool calls and browser uploads. Learn how discovery, DLP, data lineage and tokenization protect it in 2026
· Customer PII, PHI, and payment data now leavesthrough channels that didn't exist in most security programs three years ago:AI prompts, browser uploads, and AI agents with standing access to yoursystems.
· Youcan't protect what you haven't found. Discovery and classification across SaaS,cloud, and endpoints comes before any control.
· Detection isn't protection. Redact, mask, block,alert, delete, label, or revoke access; the response has to fit the data type.
· Content matching alone misses renamed and copiedfiles. Data lineage tracks where a file came from, not just what's inside it.
· AI agents need their own control layer. If anagent can query Salesforce or Snowflake, its tool responses carry customer datatoo.
· Tokenization keeps regulated data off yourservers entirely — the strongest option when you control the application.
Why Customer Information Is Harder to Protect Now
Customers hand your business information constantly, and the most sensitive slice of it is personally identifiable information (PII) — anything that uniquely identifies a person. Social security numbers, driver's licenses, credit card numbers, addresses, phone numbers, bank accounts, biometric identifiers. Add PHI if you touch healthcare, and payment data if you take cards.
None of that is new. What changed is the number of doors.
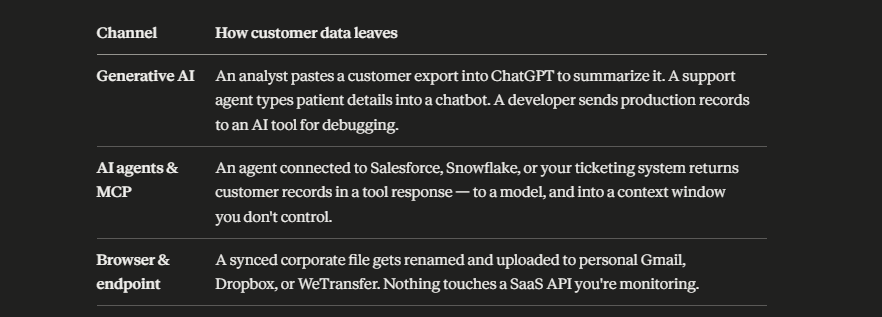
A few years ago, customer data leaked through a predictable set of channels: email, chat, cloud storage, support tickets, and application logs. Those channels are still there. But three more opened, and they move faster than anything before them:
The old channels leaked slowly and left traces. A file in the wrong Drive folder is discoverable and recoverable. Data pasted into a prompt is ingested into a model. There's no file to find and no share link to revoke.
A Regulatory Environment That Keeps Expanding
Exposing customer data puts customers at risk. It also puts the business at risk, and the compliance surface has only grown.
Under the EU's GDPR, users have a right to be forgotten — which is close to impossible to honor if you don't know every place a person's data lives. The California Consumer Privacy Act grants similar rights, and a long list of US states have followed with their own statutes. PCI DSS governs anyone handling card data, with fines or loss of processing on the line. HIPAA governs PHI. SOC 2 and ISO 27001 govern whether your enterprise customers will sign at all.
Two things make this harder than it used to be:
Consumer AI tools rarely come with the paperwork. A free-tier assistant has no BAA and no DPA, and may retain what you submit. Regulated data going into one isn't a policy violation you can remediate later — it's a disclosure.
Data subject requests assume you have an inventory. "Show me everything you hold about this person" is a discovery problem before it's a legal one.
The Two Root Problems
Both classic challenges still apply, and both got worse.
Data moves through channels nobody authorized. A customer pastes their card number into a support ticket to get help faster. An employee forwards a spreadsheet to a personal address to work on it at home. Neither is malicious, and both expose customer data to people without clearance to see it. Insider incidents alone cost US companies millions annually, and the tools that data lands in are themselves targets — Slack has been compromised before.
Data duplicates faster than teams can secure it. An engineering team builds a new signup form that captures names, addresses, and card numbers into a fresh database. Your organization already had that data in three other places. Now it sits in four, each secured differently, each a separate breach surface — and each one you'll need to search the next time a deletion request arrives.
AI adds a third: data gets copied into places that don't behave like data stores at all. A model's training set, a vector database, an agent's context window, a prompt log. Traditional inventory tooling doesn't see any of it.
✨ Start With Discovery, Not Controls
Most programs fail here. They buy enforcement before they know what they hold.
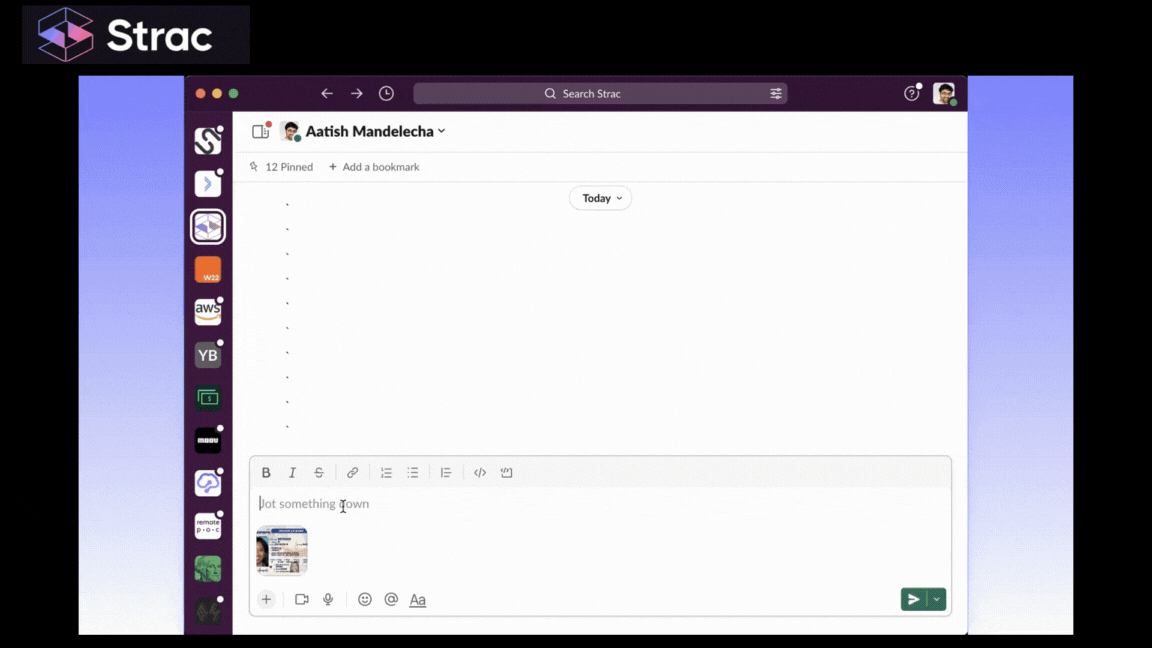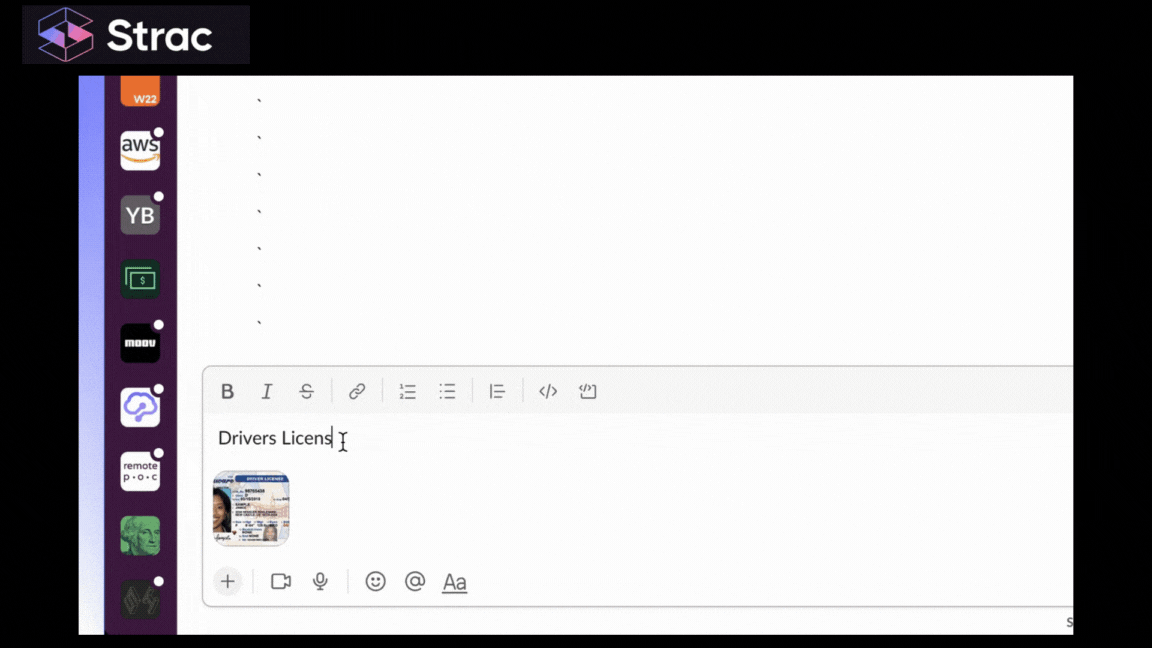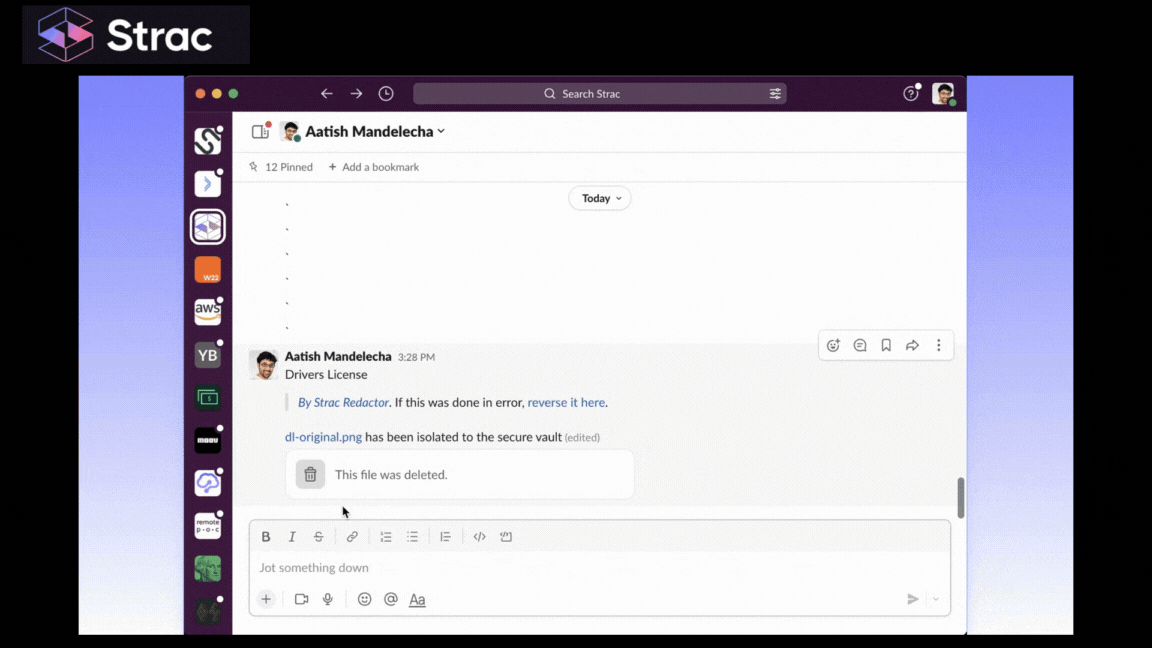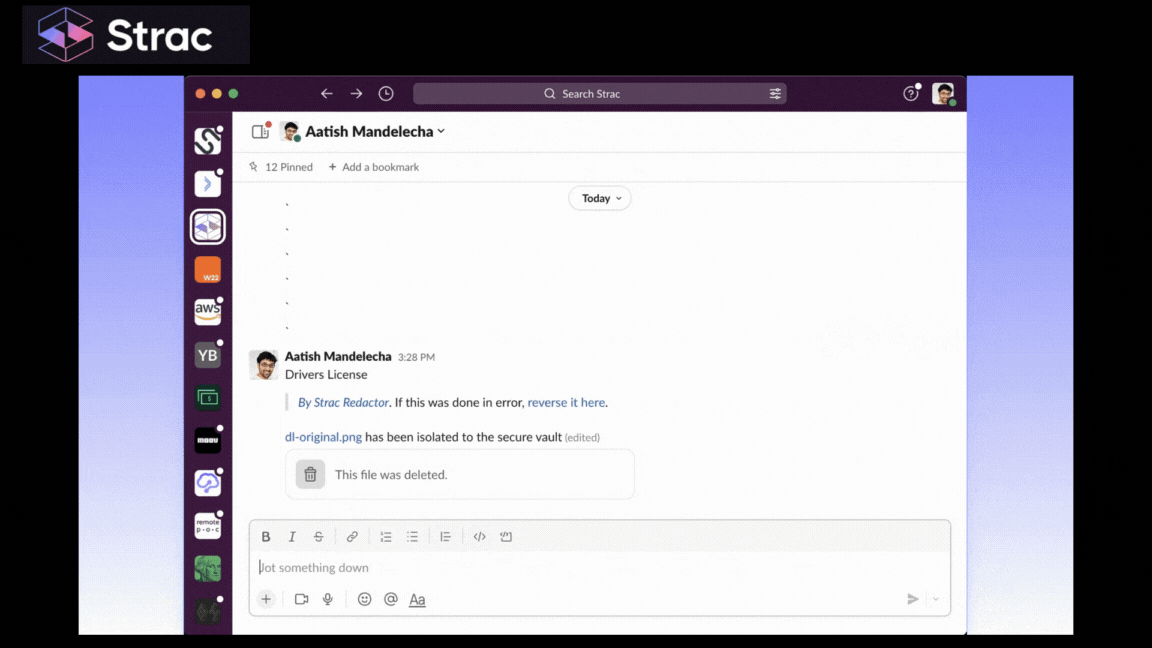
Effective discovery and classification runs continuously across every surface where customer data lands — SaaS applications, cloud storage, databases, and endpoints — and reads unstructured content, not just database columns. Customer PII lives in PDFs, Word documents, screenshots, and scanned forms as often as it lives in tidy tables. A scanner that can't read a JPEG of a driver's license isn't giving you an inventory.
What you want out of discovery:
Where sensitive data actually is — by app, by store, by endpoint
What kind it is — PII, PHI, PCI, or your own confidential categories
Who can reach it — including public links and external shares
How exposed it is — so you can rank remediation instead of drowning in findings
This is the DSPM layer, and it's what turns "we probably have card data somewhere" into a list you can act on.
✨✨Data Loss Prevention: Match the Response to the Data
Detection tells you sensitive data is moving. DLP decides what happens next — and the useful part is that the answer isn't always "block."
Strac's remediation options let you fit the response to the data type and the context:
Redact or mask — strip the sensitive values and leave the rest usable, so a support agent can still work the ticket in Zendesk, Slack, Office 365, or Google Workspace
Block — deny the paste, upload, or file open when the risk is too high
Warn and coach — tell the user in the moment, let them proceed with logged justification, and point them at the approved tool instead
Revoke access — kill public and external sharing on Google Drive, SharePoint, OneDrive, and Box
Delete or label — remove it where it never should have been, or classify it so downstream controls apply
Coverage matters as much as the action. Customer data doesn't respect your integration list, so enforcement has to reach SaaS applications, the browser, the endpoint, and cloud storage — with one policy and one audit trail behind all of them.
✨ Data Lineage: Track Where Files Came From
Content matching has a blind spot. RenameCustomer-List-Q3.xlsx to notes.xlsx, copy it into a local folder, and a scanner looking only at filenames and patterns can lose the thread.
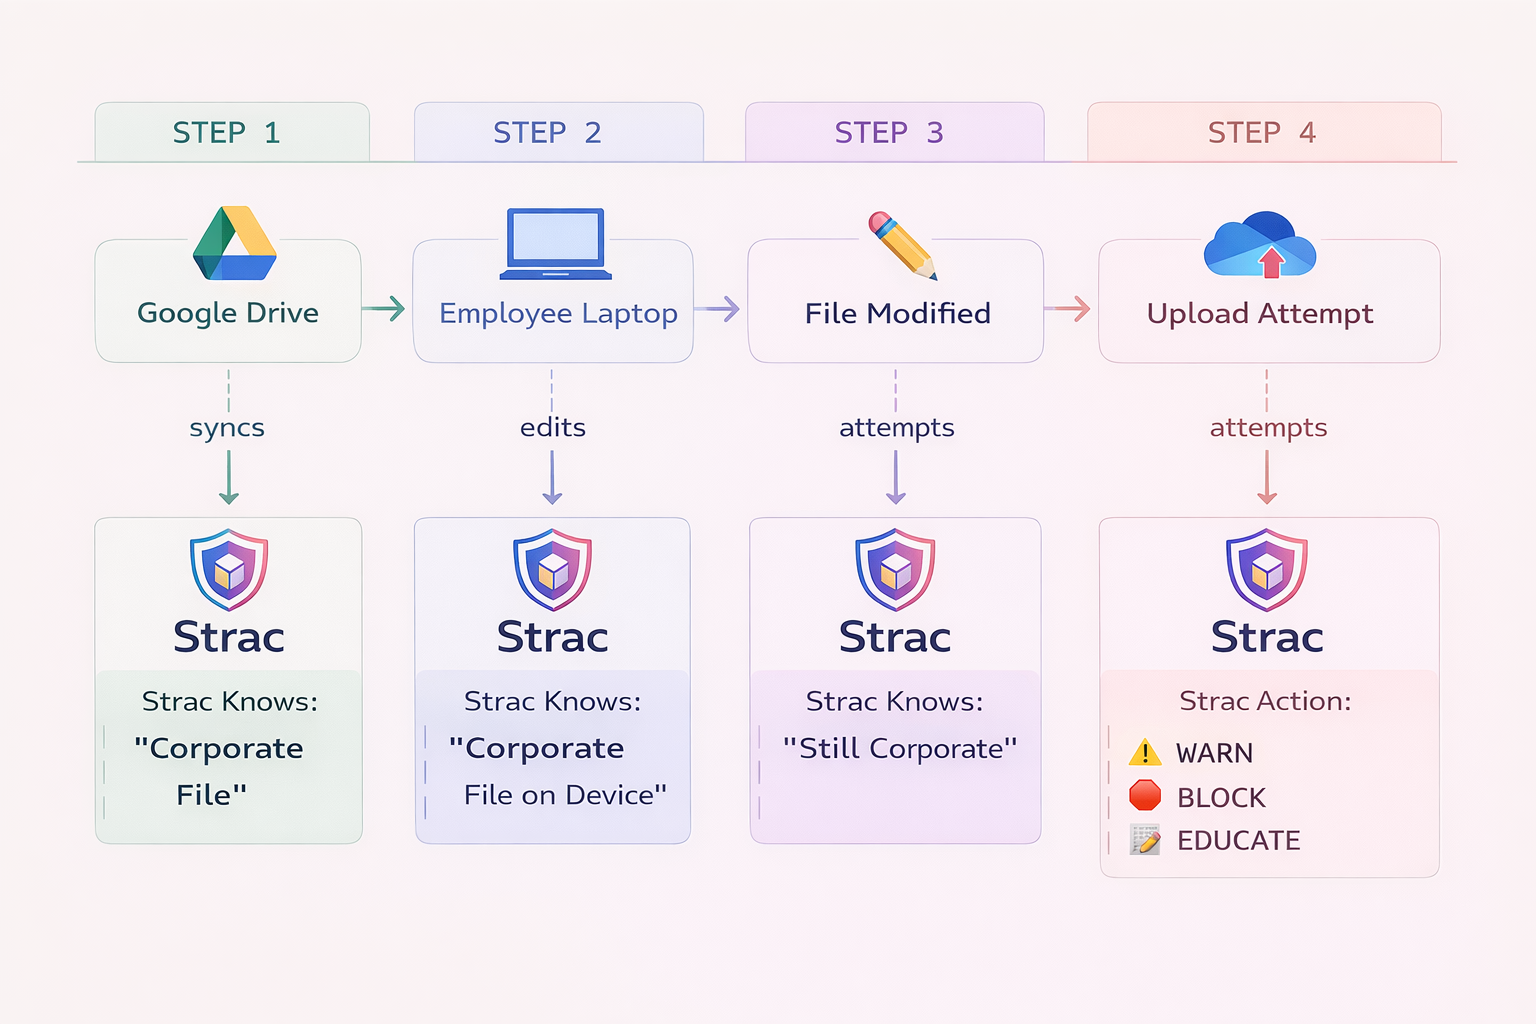
Endpoint data lineage solves this by tracking file origin. Files synced from Box, Google Drive, OneDrive, or SharePoint stay identified as corporate data even after renaming, editing, or copying. When someone tries to upload one to personal Gmail, Dropbox, WeTransfer, or an AI tool, the browser-level control catches it before the data leaves — and you can warn, educate, redirect to an approved alternative, or hard-block depending on what the file holds.
Worth noting for anyone who has to sell this internally: the endpoint agent does this with no keystroke logging and no screen recording. It scans synced cloud folders and watches destinations, not employees. That distinction is usually what gets an endpoint rollout approved.
✨ Governing AI and AI Agents
This is where customer data protection has changed most.
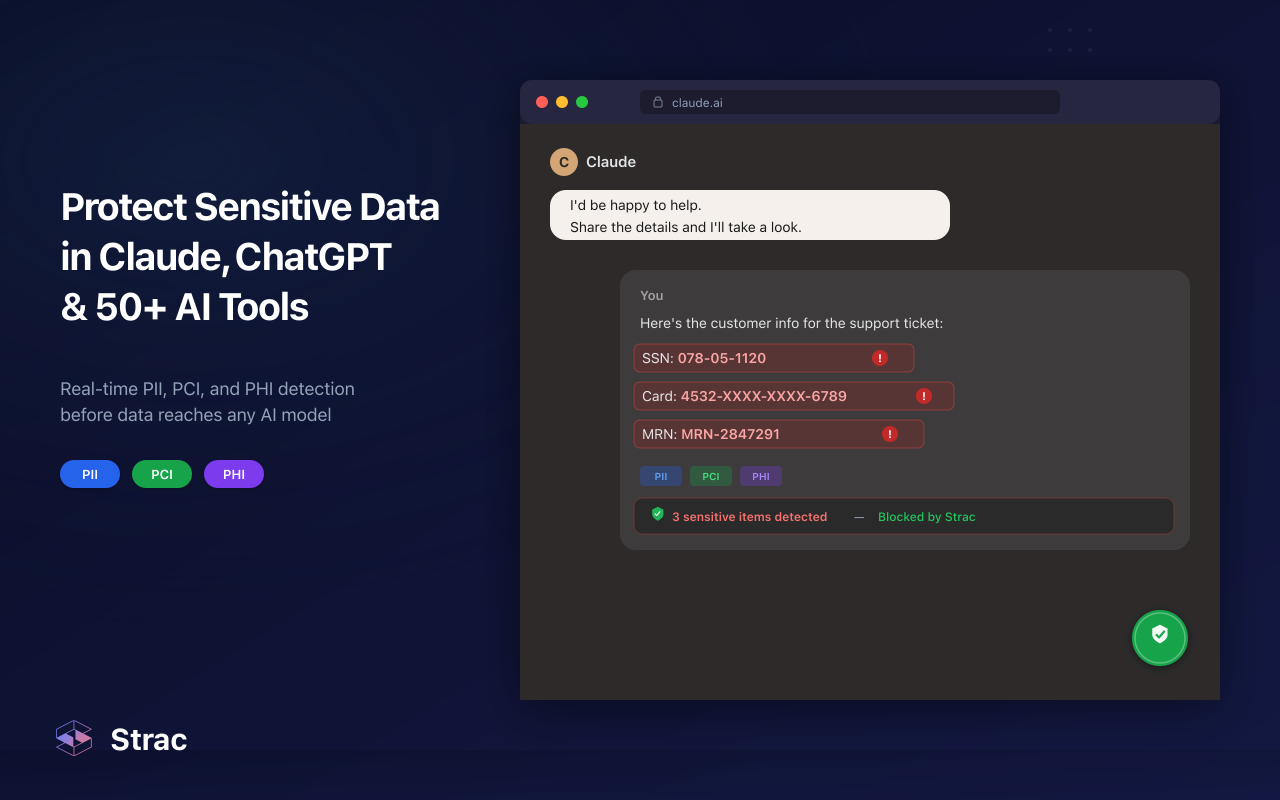
Gen AI DLP covers the human-in-a-browser case. When an employee pastes or uploads customer data into ChatGPT, Claude, Gemini, or Copilot, inspection happens before submission — redacting the PII, blocking the upload, or warning the user. You also get visibility into which AI tools your organization is actually using, which is usually a longer list than anyone expects.
👉 Read our blog on AI DLP to learn how AI DLP prevents sensitive data exposure in ChatGPT, Claude, Copilot, Gemini, and other AI applications.
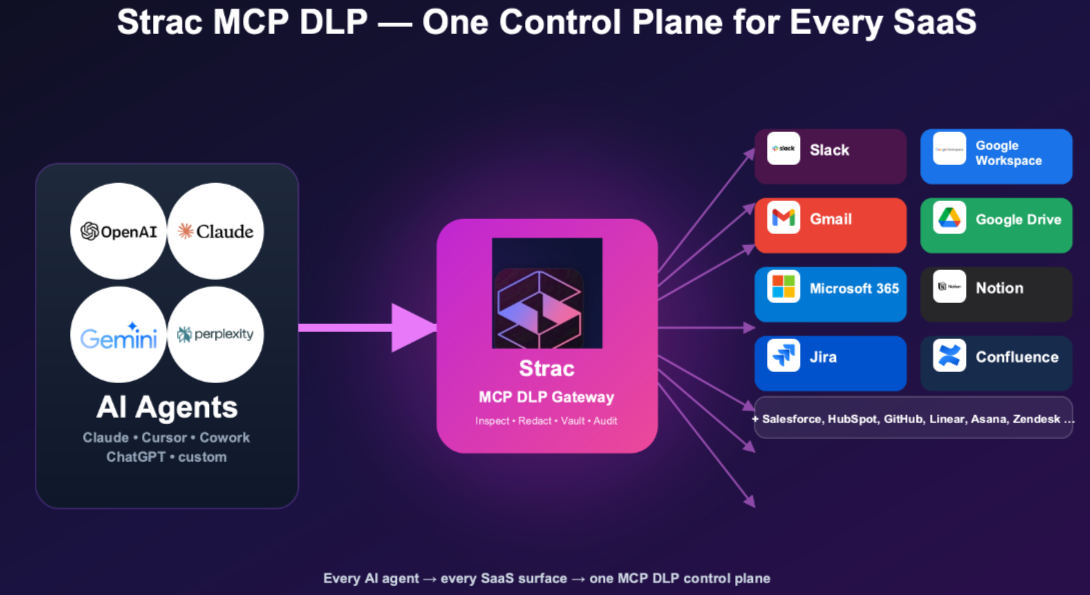
MCP DLP covers the case most programs haven't addressed yet: agents. When an AI agent connects to Salesforce, Slack, Snowflake, or GitHub through a connector, it reads real customer records and returns them in tool responses. Those responses flow into a model. Controlling that means redacting sensitive data in the tool response itself and monitoring what each agent accesses — least privilege applied at the data layer, not just the OAuth scope.
If you're allowing AI at all — and most organizations are — these two layers are the difference between governed adoption and a disclosure you find out about later.
✨ Tokenization: Keep the Data Off Your Servers
The strongest control is not holding the data in the first place.
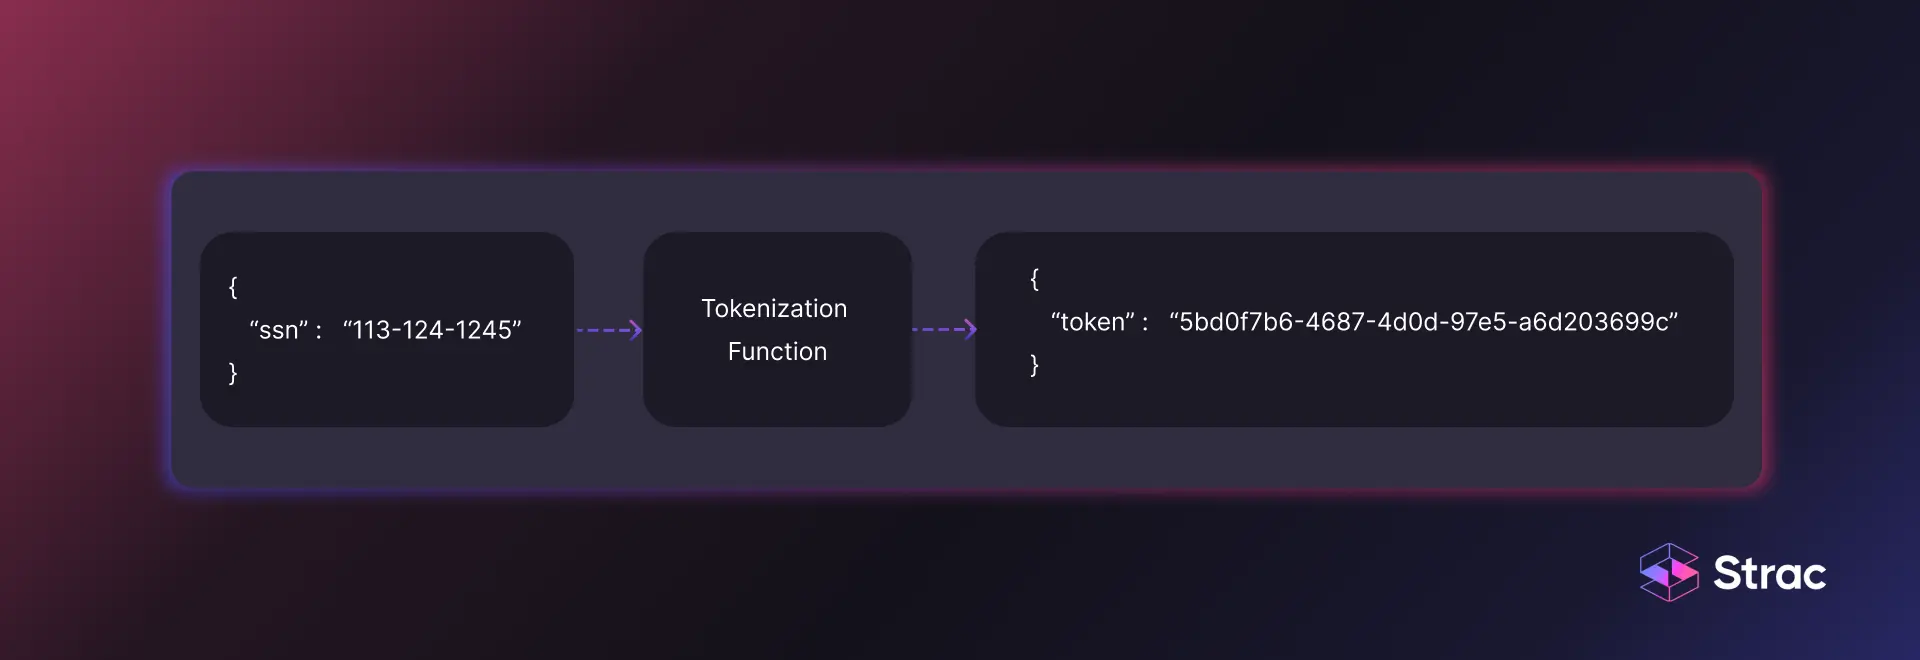
Tokenization replaces a real identifier — a card number, an SSN, a government ID — with a token that has no intrinsic meaning or value. It's de-identification: the token is useless to anyone who steals it, and the real value stays in a vault you don't operate.
Strac's UI components and proxy APIs let you tokenize at the point of collection across web, iOS, and Android. The sensitive value never touches your servers, which shrinks your compliance scope rather than just securing it — a meaningfully faster path to PCI DSS, HIPAA, and SOC 2 than building vaulting yourself.
Use tokenization where you control the application and the data is structured and regulated. Use DLP and lineage everywhere else, because most customer data leakage happens in places you didn't build.
✨ Putting It Together
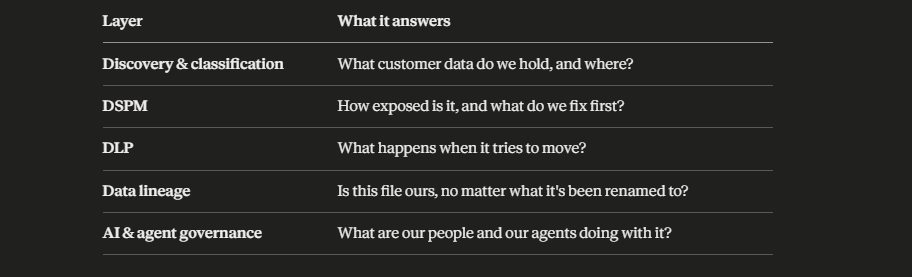
A modern customer data protection program has five layers, in this order:
Then tokenization underneath, wherever you own the collection point.
You don't need all five on day one. You do need to start with discovery, because every other layer depends on knowing what you have.
🎥 How Strac Protects Customer Data Everywhere It Lives or Leaks
Most tools cover one surface well and leave gaps at the seams — a SaaS scanner that can't see the endpoint, an endpoint agent blind to what's shared in Drive, a browser extension that knows nothing about your databases. Customer data doesn't respect those boundaries. It gets exported from Salesforce, saved to a laptop, renamed, pasted into a chatbot, and attached to a support ticket, all in one afternoon.
Strac covers the whole path with one detection engine, one policy set, and one audit trail.
Where it lives. Strac discovers and classifies PII, PHI, and PCI across SaaS apps, cloud stores, endpoints, and on-premise file shares — including PDFs, spreadsheets, and images, so a scanned ID is detected like any other record.
Where it leaks. The same engine enforces in real time on every exit route: email and chat, support tickets, cloud sharing, browser uploads, generative AI, AI agent tool responses, and application logs. Where you own the collection point, tokenization keeps the data off your servers entirely.
Three things make that work as one system rather than four:
One classification engine — a PCI detector behaves identically in Slack, on a laptop, and in an agent's tool call, so a policy means the same thing everywhere
A graduated response — redact, mask, block, warn, delete, label, or revoke, matched to the data type instead of one blunt action
One audit trail — evidence for HIPAA, PCI DSS, SOC 2, ISO 27001, GDPR, and CCPA in a single place, with no keystroke logs or screen recording anywhere in the product
So when a deletion request arrives, or an auditor asks where cardholder data lives, or someone pastes a customer list into a chatbot, you're answering from one system.
Conclusion
Protecting customer information is still about the same two instincts — don't let data go where it shouldn't, and don't hold what you don't need. What's changed is the speed and the surface. Data now leaves through a prompt, an agent's tool call, or a renamed file in a browser upload, and none of those look like the channels most programs were built to watch.
The organizations getting this right in 2026 aren't the ones with the strictest policy. They're the ones who know exactly what customer data they hold, watch every surface it can move across, and put the right response — redact, block, warn, revoke, or tokenize — at the moment it moves.
What counts as customer information you have to protect?
PII such as SSNs, driver's licenses, addresses, phone numbers, bank accounts, and biometric identifiers; PHI if you handle health data; and cardholder data under PCI DSS. If it identifies a person or unlocks an account, treat it as regulated.
How do you stop employees leaking customer data into ChatGPT or Claude?
Inspect at the point of submission. Content-aware DLP on the browser and endpoint can redact the PII, block the upload, or warn the user before the prompt is sent — without keystroke logging or screen recording.
What about AI agents that read customer records directly?
Agents connected through MCP return real customer data in tool responses. That needs its own control: redact sensitive values in the tool response and monitor what each agent accesses, rather than trusting the OAuth scope alone.
Is tokenization better than DLP?
They solve different problems. Tokenization keeps regulated data off your servers where you control the application. DLP protects data everywhere else — SaaS, email, chat, cloud storage, browser, and endpoint. Most organizations need both.
How does data lineage differ from normal content scanning?
Content scanning asks what's inside a file. Lineage asks where it came from. Tracking origin means a corporate file stays identified as corporate even after it's renamed, edited, or copied locally.
Where should we start?
Discovery. Find and classify customer data across SaaS, cloud, and endpoints first, rank it by exposure, then apply controls to the highest-risk stores. Buying enforcement before you have an inventory means enforcing on guesses.
Discover & Protect Data on SaaS, AI, MCP, Endpoints & Cloud
Strac provides end-to-end data loss prevention for all SaaS and Cloud apps. Integrate in under 10 minutes and experience the benefits of live DLP scanning, live redaction, and a fortified SaaS environment.