

September 8, 2026

5
min read
How to add Custom Data Elements (Regex rules) to Strac DSPM & DLP Platform?
How to add Custom Data Elements (Regex rules) to Strac DSPM & DLP Platform?
· A Custom Data Element is a regex rule,optionally paired with keywords and a proximity window, that teaches Strac todetect an identifier unique to your business: an employee badge number, amatter code, a partner contract reference, an internal account ID.
· The risk changed in 2026 because the exit routesmultiplied. A proprietary account number now leaves through a prompt box, anagent tool call over the Model Context Protocol, a browser paste, or a filecopied to a USB drive, and none of those look like the file share your policywas written for.
· Standard catalogs cover what regulators name.They do not cover what your business names, so the data that identifies yourcustomers inside your own systems travels unclassified.
· Strac lets you define the pattern once andenforce it everywhere: AI DLP in the browser, MCP DLP on every agent tool call, endpoint DLP on the device, and SaaSand cloud at rest.
· Customdetection is one control inside a wider program. Start from the pillar on AI data governance.
A Custom Data Element is a detector you define. You give Strac a regular expression, a name, and optionally a set of supporting keywords and a distance window, and Strac treats every match as a sensitive data class alongside its machine learning detectors for PII, PHI, PCI, secrets and source code.
The difference between the two is the difference between a compliance catalog and a business inventory. A standard detector knows a Social Security number because every organization has them. It has no way to know that ACC-88213094 is the number that identifies one of your customers in your billing system.
Once the rule exists, it behaves like any other data class in the platform. It shows up in discovery results, it drives data classification labels, it triggers policy, and it can be redacted in line rather than only reported after the fact.
Strac ships a deep catalog of sensitive data elements: identity documents across dozens of jurisdictions, patient identifiers, payment instruments, API keys, crypto secrets, network addresses. That catalog is built from formats the whole market shares.
Your most sensitive strings are usually not on it. Legal teams key everything to a matter number. Manufacturers key everything to a part and lot number. Healthcare operators run internal member IDs beside the regulated ones. Those identifiers are the join key to the record, which means they carry the same exposure as the record itself.
A standard catalog tells you what regulators care about. A custom data element tells Strac what your business cares about.
The gap used to be tolerable because proprietary IDs mostly sat inside systems you controlled. That is no longer true. The same string now moves through generative AI prompts, agent tool calls, browser sessions and personal devices, which is exactly why legacy DLP fails for AI.
Not every internal string deserves a detector. The test is simple: if the identifier can be used to look up a person, a contract or a system, it belongs under policy.
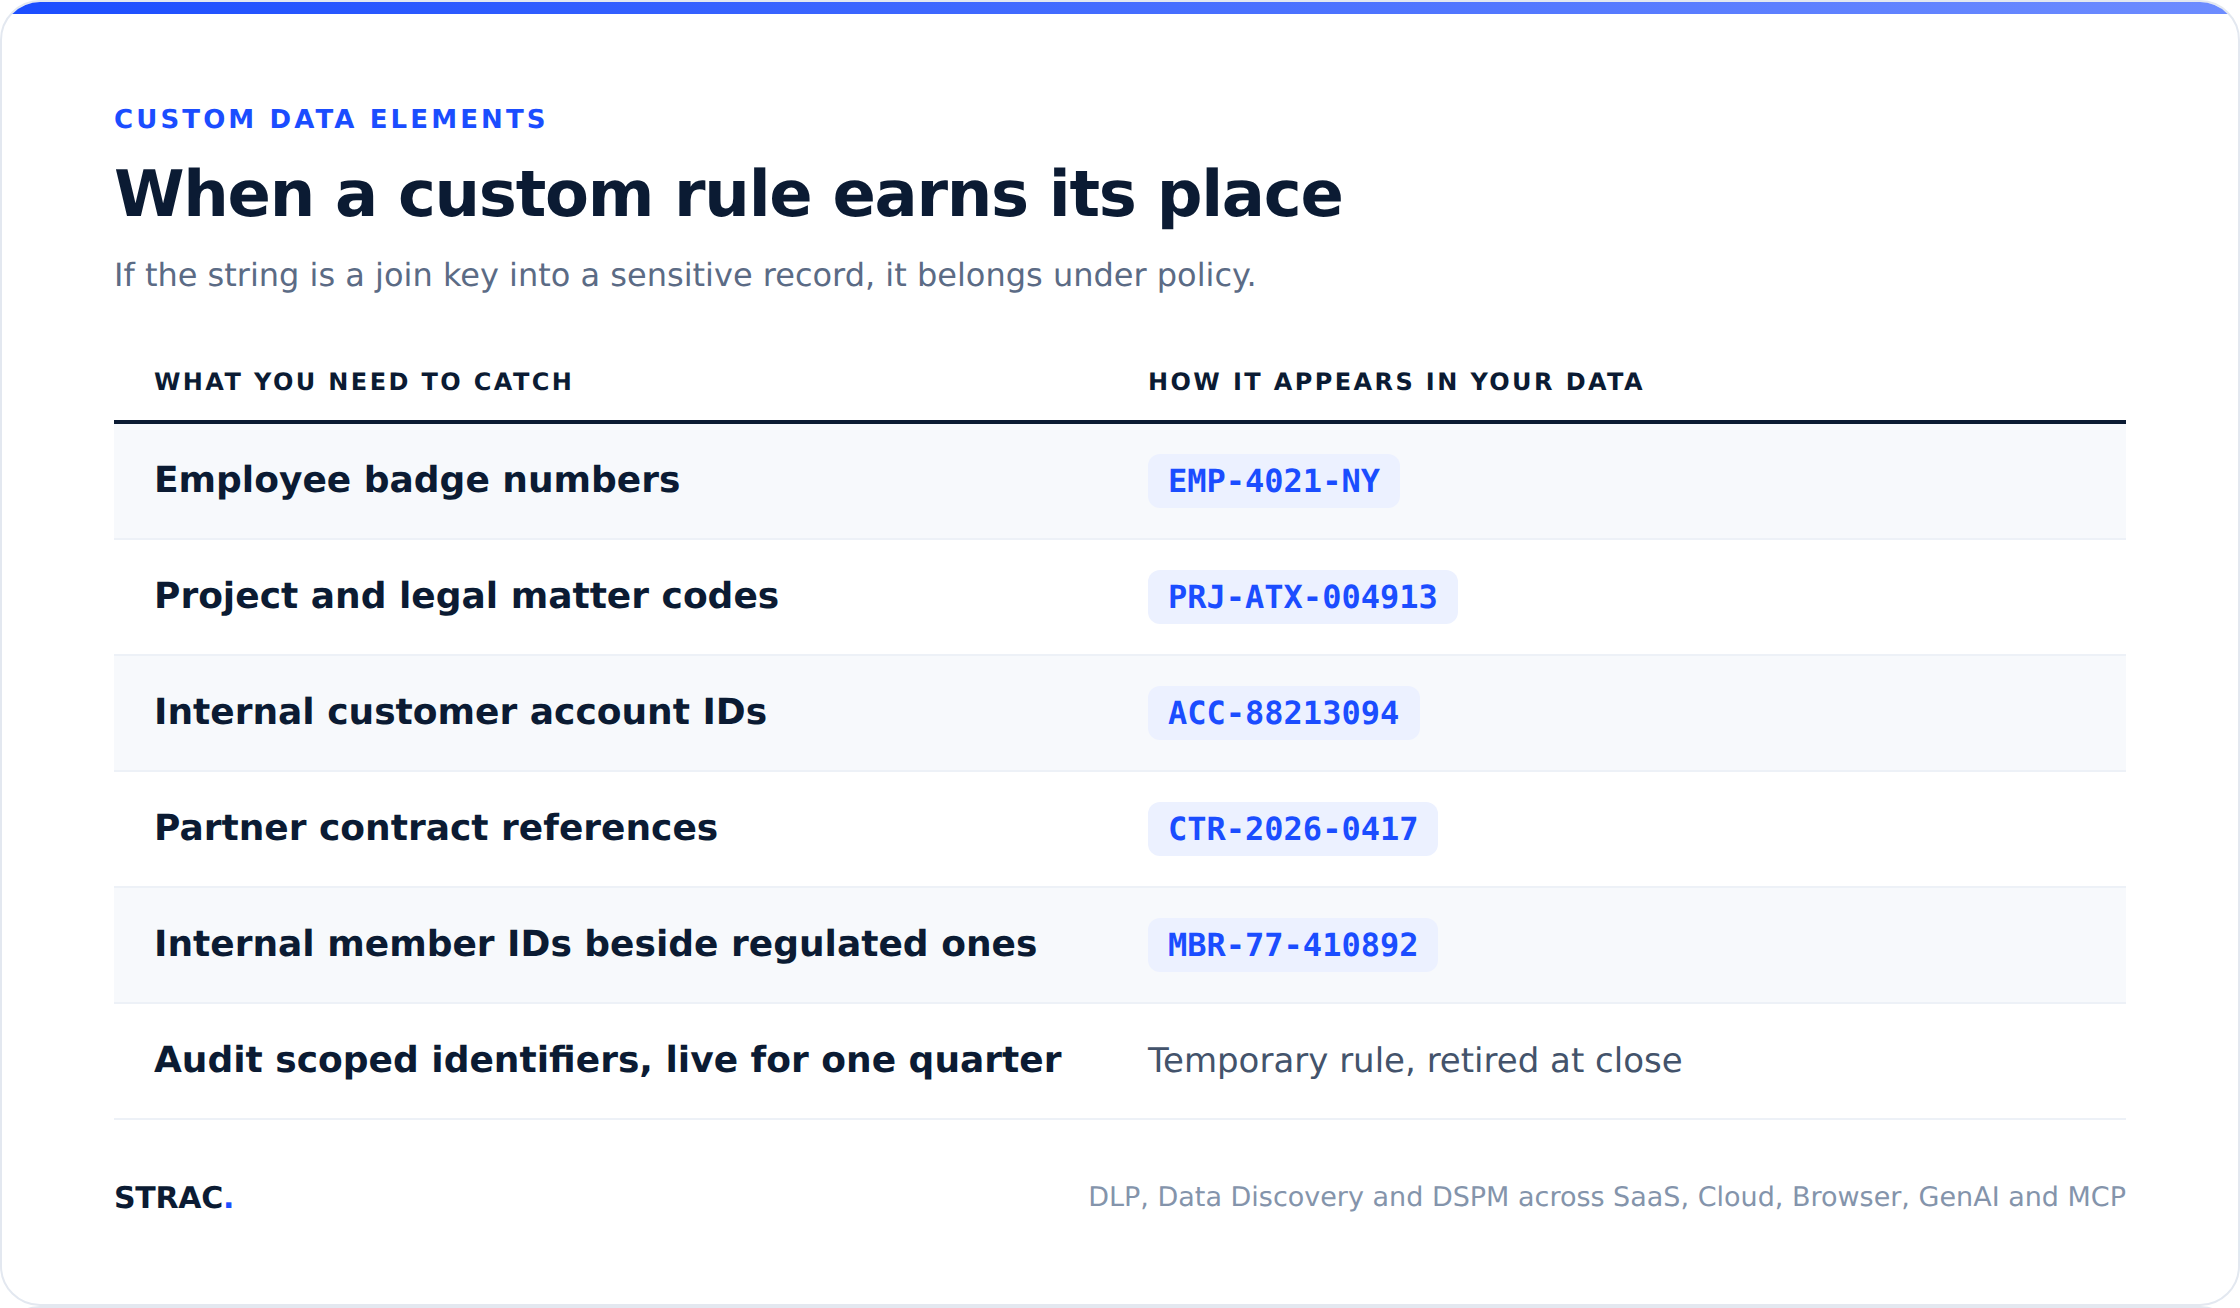
The rule of thumb: if the string is a join key into a sensitive record, treat it as sensitive.
Temporary rules are legitimate too. During an audit or an incident investigation you may need to find every occurrence of one contract reference across Slack, Google Drive, tickets and email. A custom data element gives you that sweep in hours, and you retire it when the work closes.
The flow takes about two minutes.
The detector applies to new scans immediately and to historical data on the next discovery run, so a rule added on Monday surfaces the exposure that has been sitting in a shared drive since last year.
Most custom detection projects fail on tuning, not on syntax. A pattern that matches everything protects nothing, because analysts stop reading the alerts by the second week.
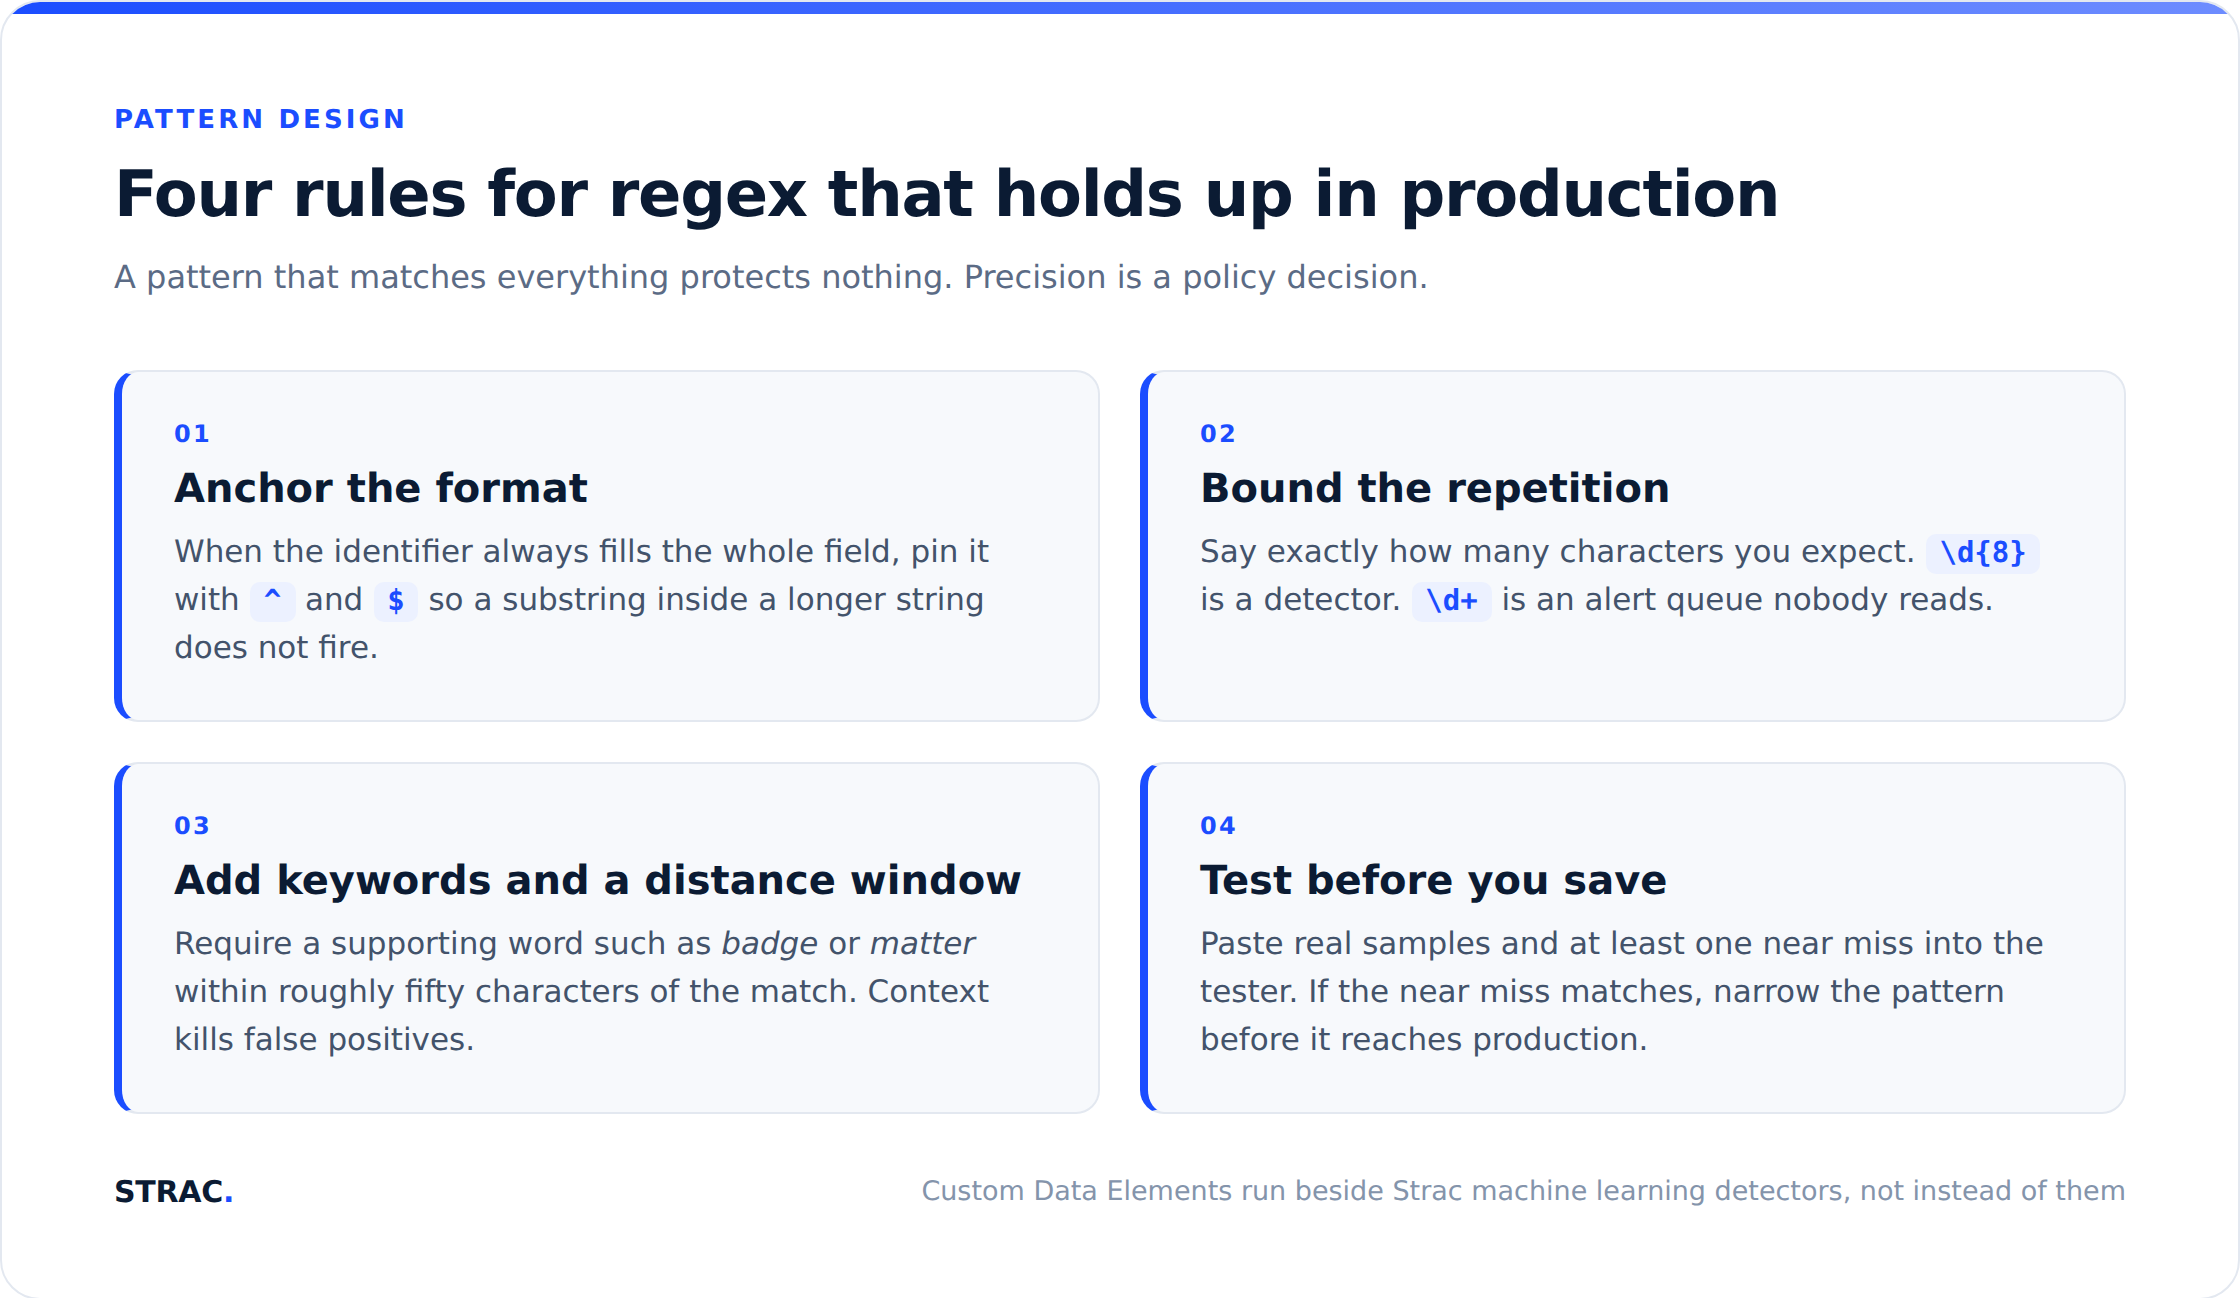
Precision is a policy decision. Every loose pattern is paid for later in triage time.
Two patterns worth copying as a starting point. An employee badge that always runs three letters, four digits and a two letter site code becomes EMP-\d{4}-[A-Z]{2}. A project code with a fixed prefix and a six digit sequence becomes PRJ-[A-Z]{3}-\d{6}. Both are bounded, both are anchored to a shape, and both pair naturally with a keyword such as badge or project inside a fifty character window.
When the format is genuinely variable, do not force it into one expression. Write two narrow rules instead of one wide one.
Definition without enforcement is a report. The value of a custom data element is that it becomes an active control on the surfaces where data actually leaves.
In the browser, AI DLP inspects the prompt before it reaches ChatGPT DLP, Claude, Gemini or Copilot, and redacts the match in place so the analyst still gets an answer and the vendor never sees the identifier. On the device, endpoint DLP watches uploads, clipboard, removable media, printing and screen capture. In agent workflows, MCP DLP inspects the content of every tool call, so an agent reading a database or a ticket queue returns redacted values rather than raw ones.
Strac detects and redacts your own identifiers on the way out, which is the backstop when identity, prompt and network controls fail.
That coverage is what separates a detector from a control. It is also how you keep shadow AI from turning into an exfiltration path: the tool may be unsanctioned, but the data reaching it is already clean.
Once the rule fires, Strac applies the same remediation ladder it uses for every other data class:
Every action is logged with the matched data class, the surface and the user, which turns a regex you wrote on a Tuesday into audit evidence for SOC 2, ISO 27001, HIPAA, PCI DSS, GDPR and the EU AI Act.
Detection tells you the identifier is moving. Remediation is what stops the leak.
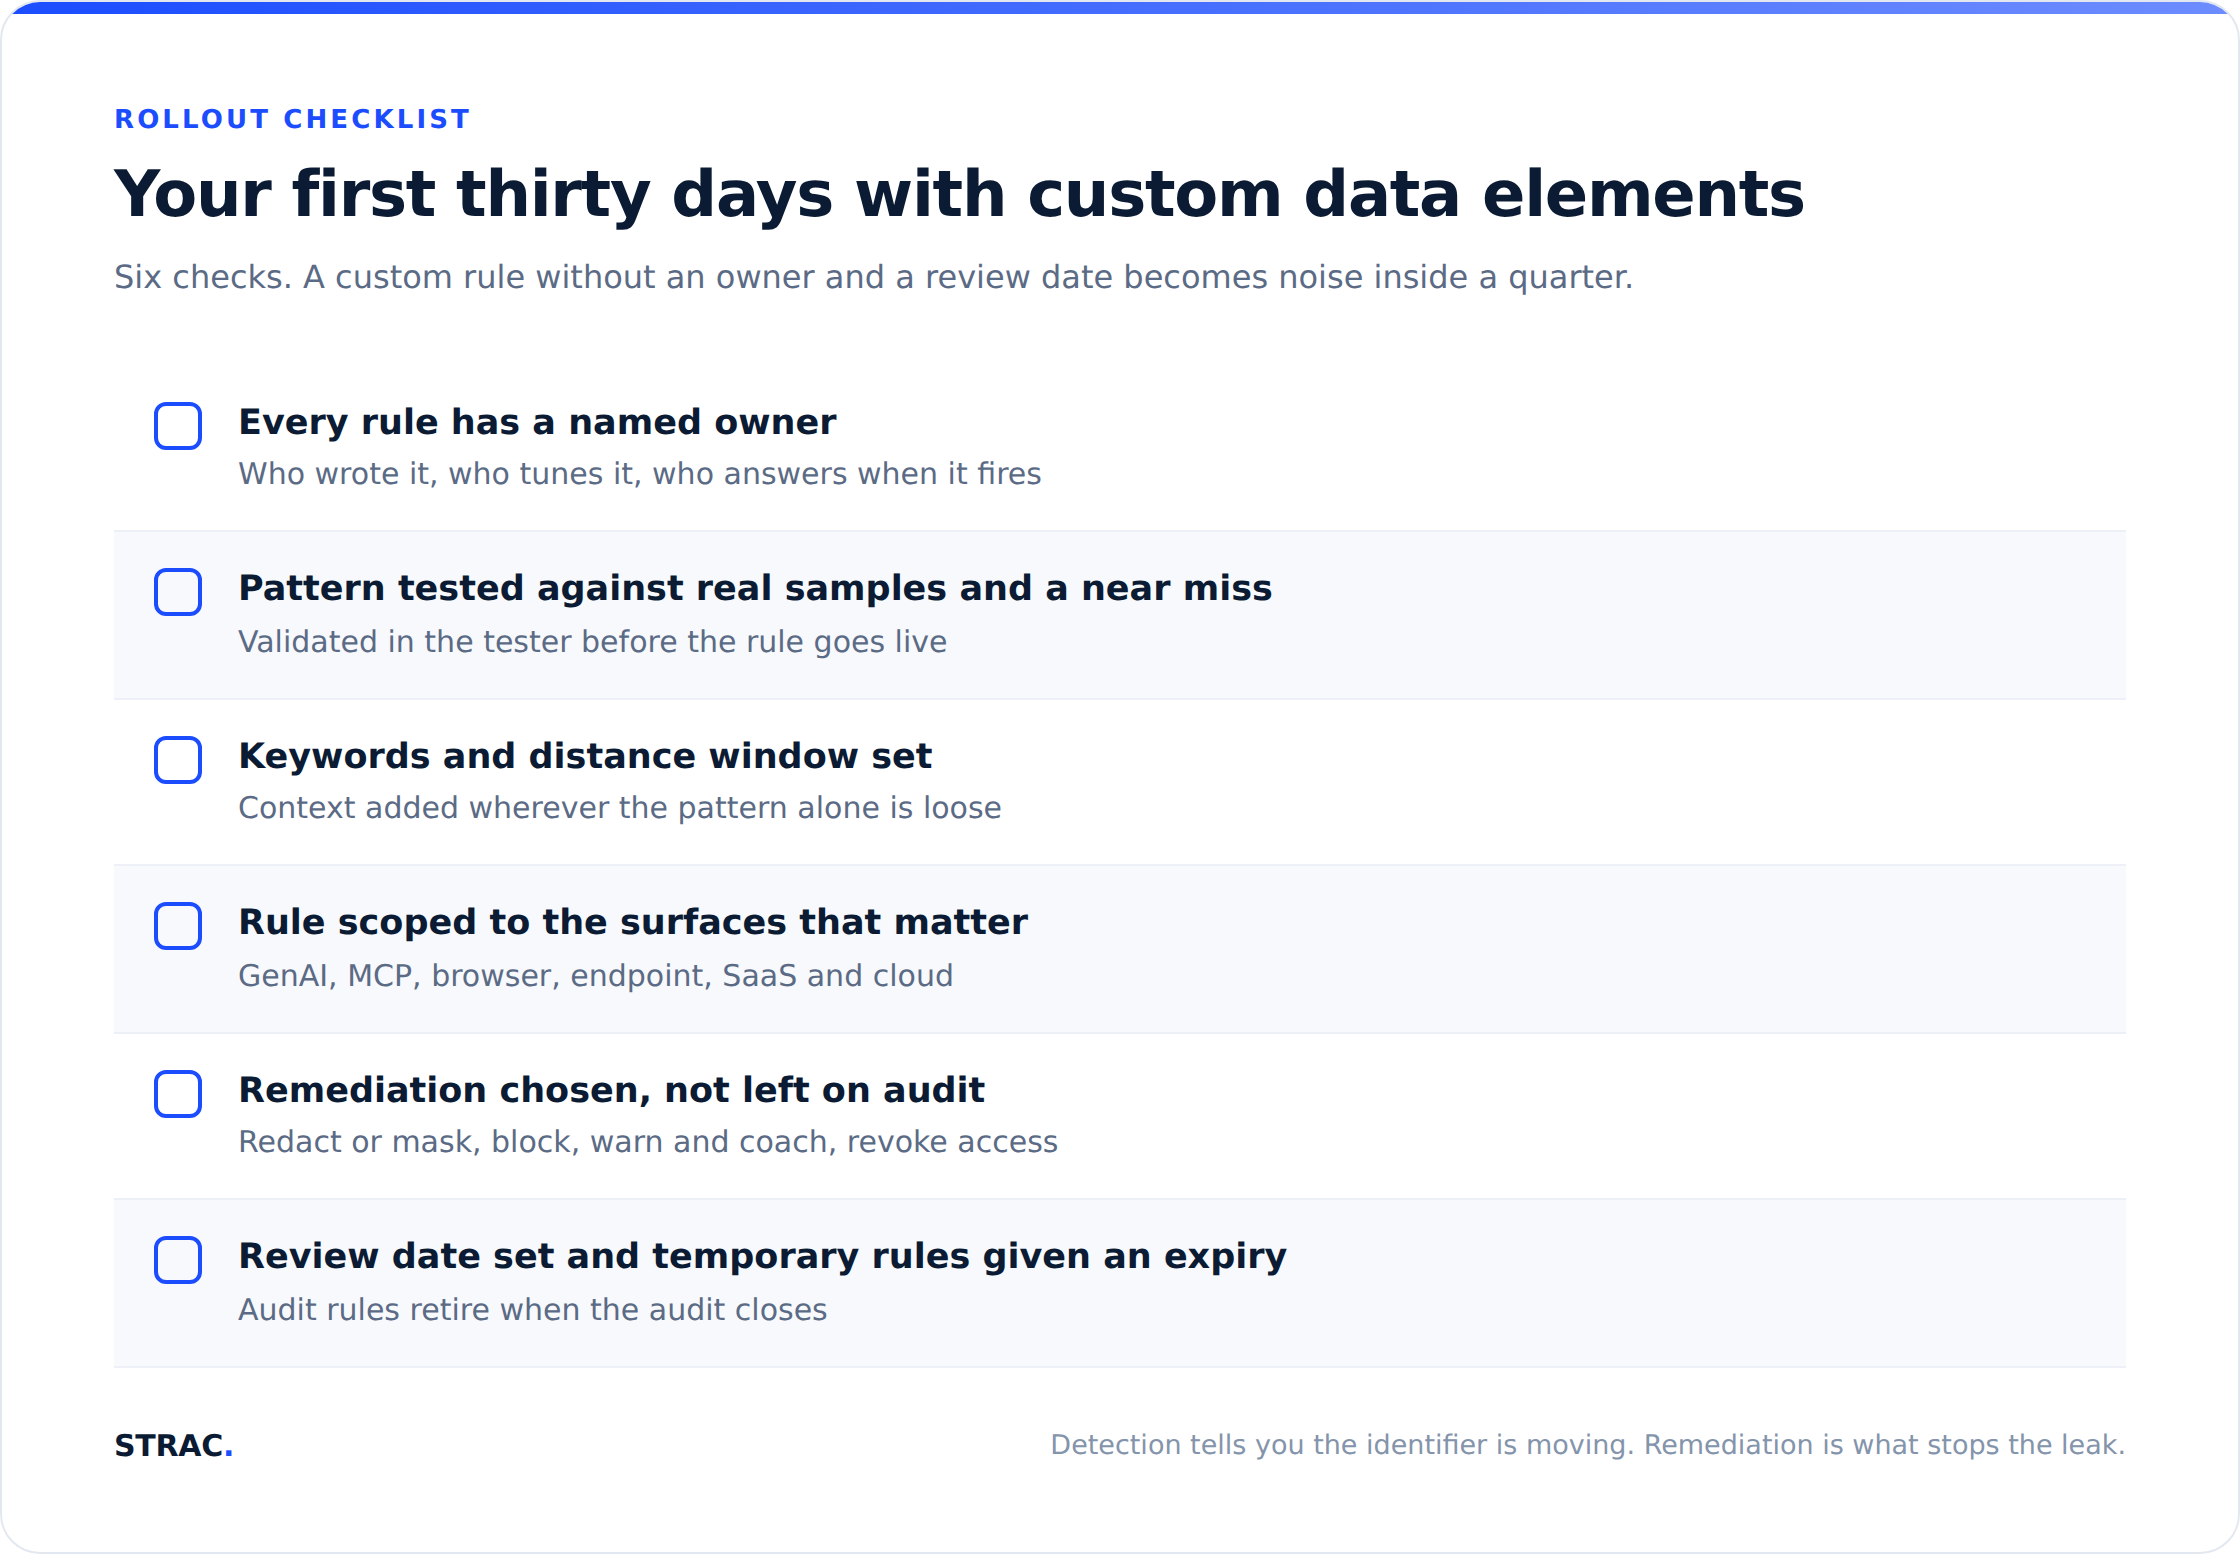
ix checks. A custom rule without an owner and a review date becomes noise inside a quarter.
Sequence it in three stages. In days 0 to 10, inventory the identifiers your teams actually use and rank them by how much of a record each one opens up. In days 10 to 20, write and test the top five patterns and run discovery across SaaS and cloud to see the existing exposure. In days 20 to 30, move from audit mode to enforcement on the highest risk surfaces first, which in 2026 means MCP DLP and the browser rather than the file server.
Related reading: AI data governance, generative AI data governance, AI agent security.
Identity controls, prompt filters and network rules all fail eventually. The data layer is the backstop, and the data layer only works if it recognizes the data you actually care about, not just the formats a compliance catalog happens to ship with.
A Custom Data Element closes that gap in two minutes and then holds across SaaS, cloud, browser, GenAI and MCP DLP, with redaction on every action so a compromise never becomes a breach.
Book a demo to see Strac detect and redact your own identifiers on every surface your teams use.
A Custom Data Element is a detector: it decides whether a string is sensitive. A label is the outcome you attach to the file or record once it is. You need both, and in Strac the detector feeds the label automatically.
Most tools scope regex to one surface, usually email or the file share. The question in 2026 is whether the same rule fires inside a prompt box and on an agent tool call. If it does not, the rule covers the exits your data stopped using.
No. The default is redaction, not blocking. The identifier is replaced with a placeholder and the user keeps working, which is why adoption holds. Blocking is reserved for destinations you have decided are out of bounds.
No. Free text references, inconsistent legacy formats and identifiers with no fixed shape defeat pure pattern matching. That is why Strac pairs custom rules with machine learning detectors and OCR, and why enforcement sits at the data layer where a miss on one rule is not a total loss.
It is the classification input that everything else depends on: discovery, labeling, policy and audit evidence. See the pillar on AI data governance and the practical view in MCP DLP for how the layers connect.







