November 12, 2026

5
min read
Private LLMs: Data Protection Potential and Limitations
Private LLMs keep the model in-house but not your data out of it. See how Strac Gen AI DLP and MCP DLP redact PII, PHI and secrets before any model sees them.
Companies turned to private LLMs because public chat tools felt risky. Employees were pasting customer records, contracts and code into ChatGPT, and nobody could see it or take it back. Hosting a model in your own cloud looked like a clean fix.
That was a reasonable first step. But the way people use AI has changed. Teams no longer just type questions into one chat window. They use ChatGPT, Claude, Gemini and Copilot side by side, run AI apps on their laptops, and connect AI agents to Slack, Google Drive, Salesforce and production databases through the Model Context Protocol (MCP).
Each of those paths moves sensitive data into a model. A private LLM changes where the model runs. It does not change what data reaches it. For a deeper look at the prompt side of the problem, see how to secure sensitive data in LLM prompts and how to avoid passing customer PII to OpenAI.
A private LLM is a model that one organization hosts and controls, on its own servers or in a dedicated cloud service such as Azure OpenAI, Google Vertex AI or Snowflake. It does give you real benefits:
Those are perimeter controls. They answer the question "where does the model live?" They do not answer "what is inside the prompt?", "who is allowed to see this answer?" or "what did the agent just read from our CRM?" Those questions are where data leaks happen today.
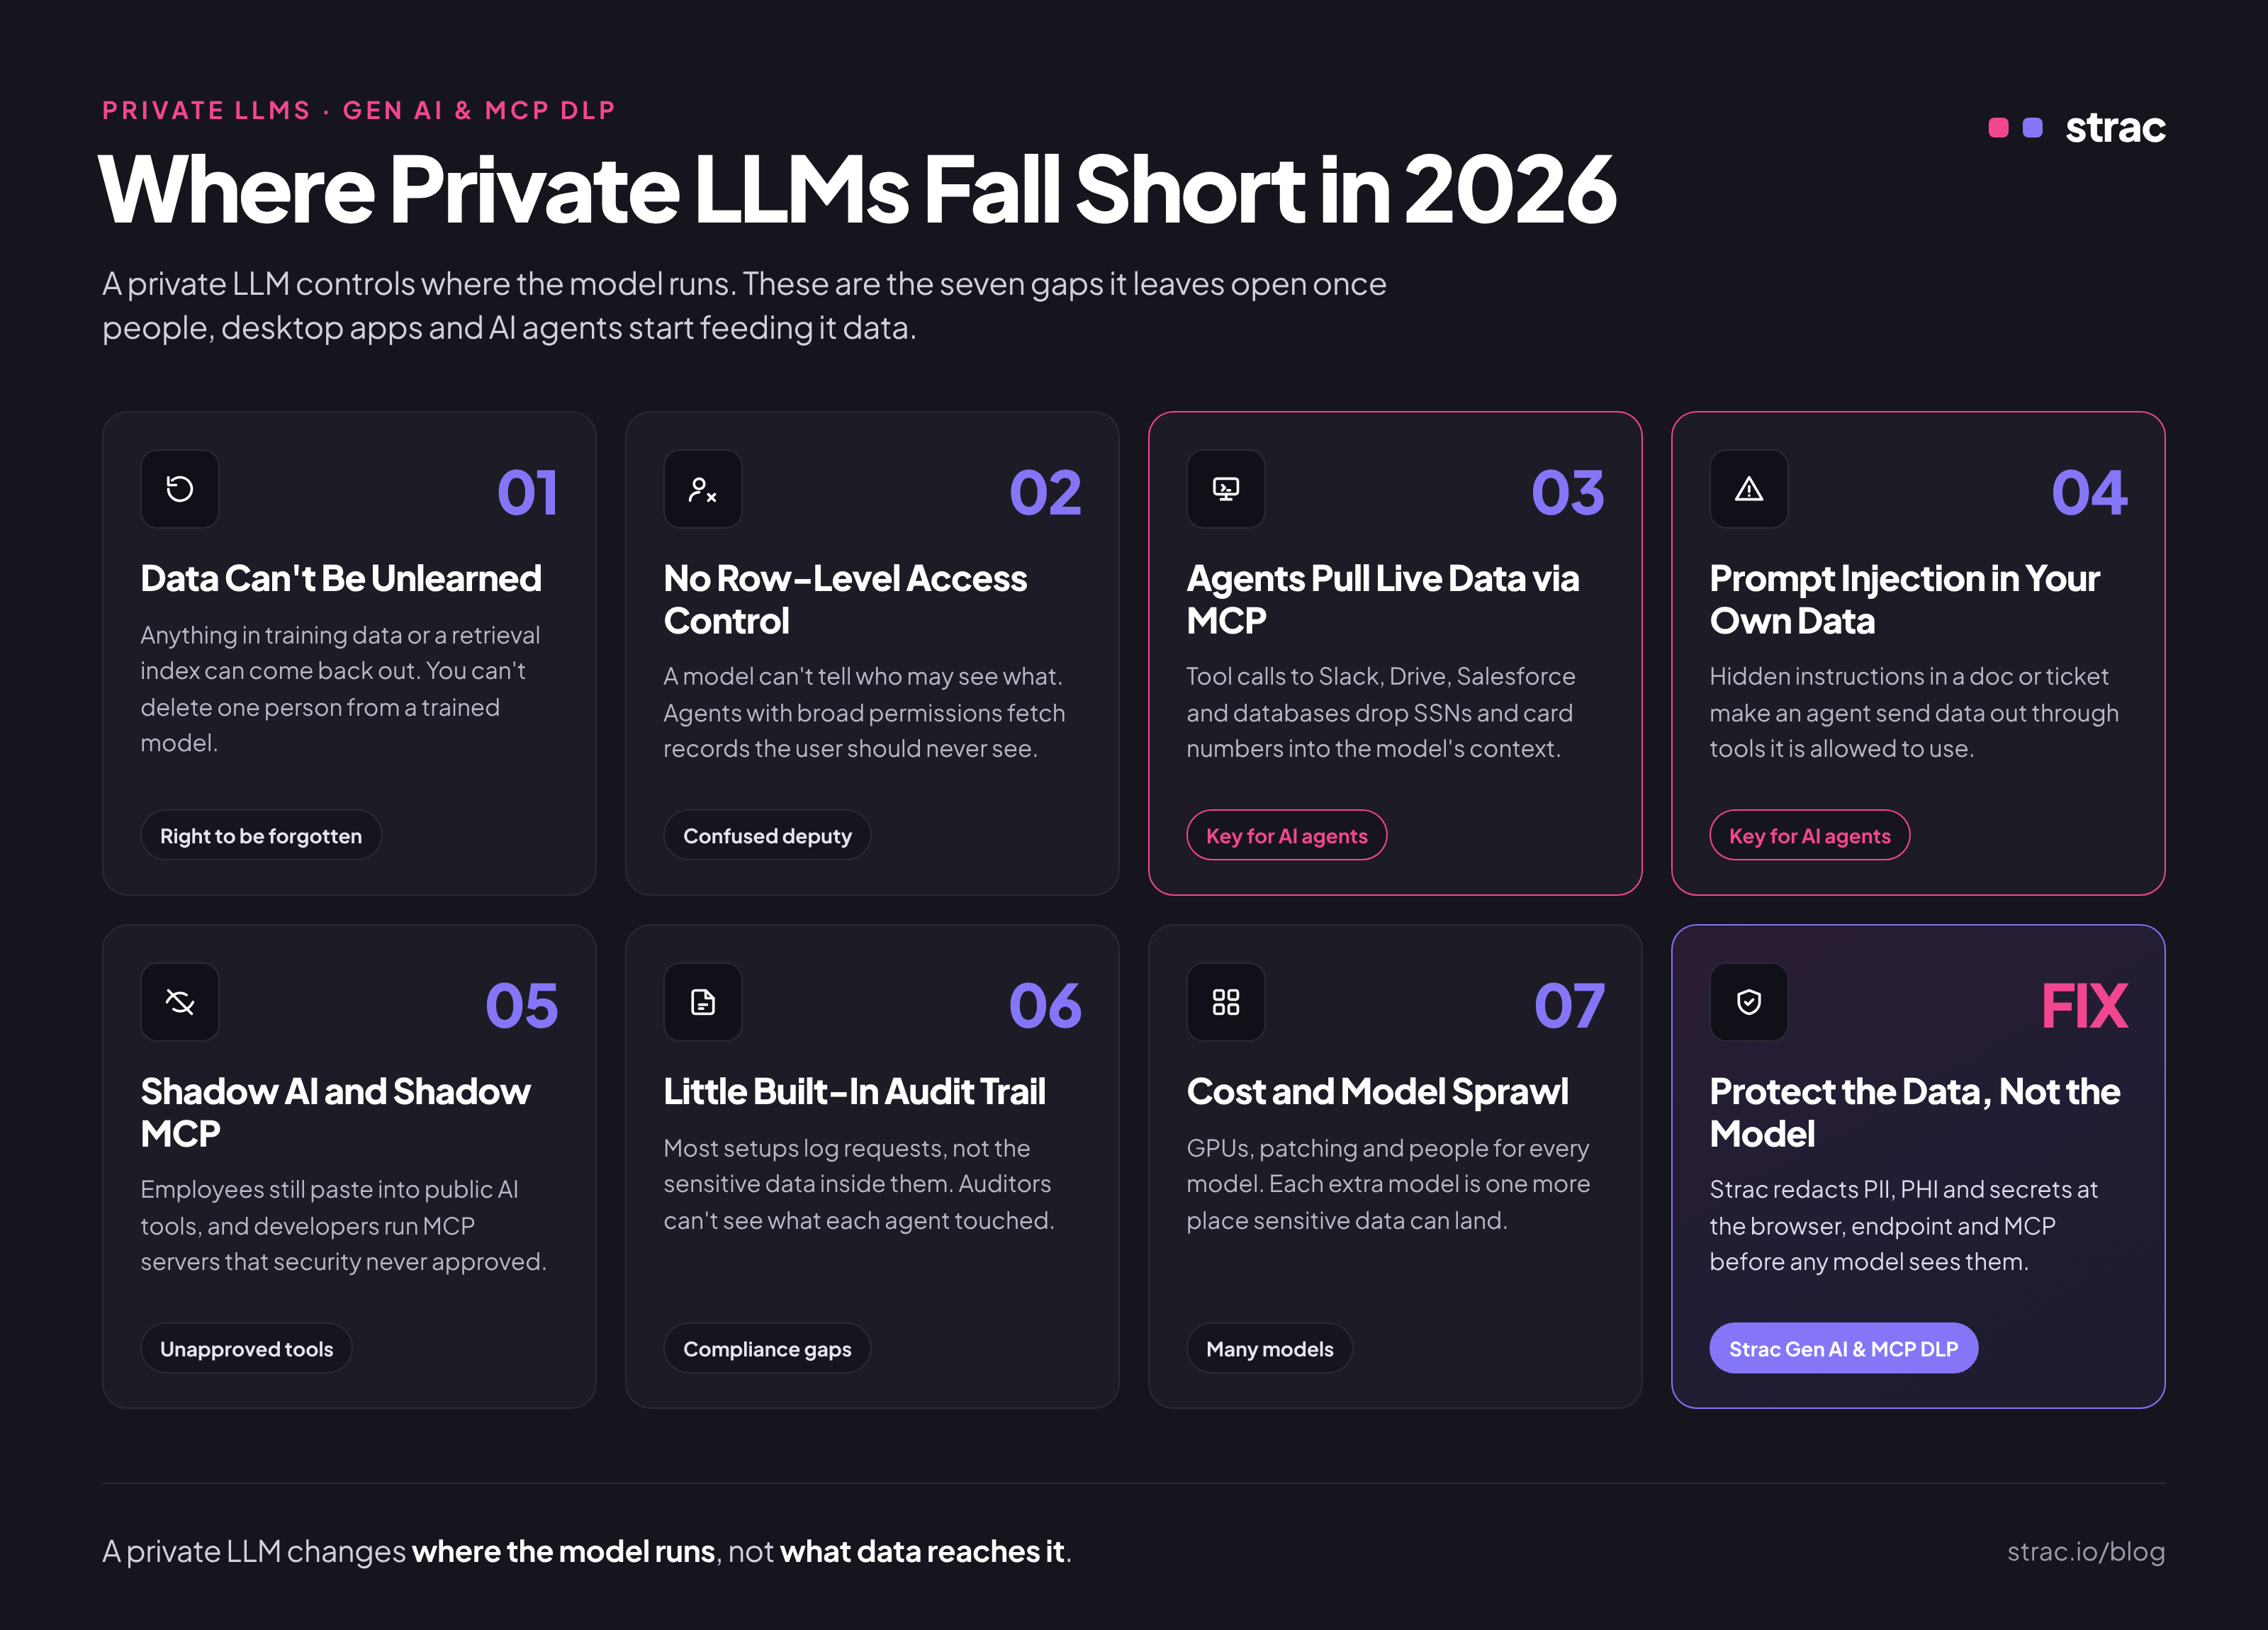
A model has no built-in way to forget one record. If customer SSNs, patient notes or API keys are in its training data or its retrieval index, any user who asks the right question may see them. GDPR and CCPA give people the right to have their data deleted, but you cannot delete one person from a trained model. The only reliable fix is to keep that data out before it goes in, using redaction, data masking or pseudonymization.
A database can stop a support agent from seeing every customer's file. A model cannot. Say a support agent, Alex, is helping a customer, Carla. Alex should see Carla's ticket, not her full card number and not other customers' records. Once that data is in the model's context, the model has no idea who is allowed to see what. With agents, this becomes the confused deputy problem: an agent with broad permissions fetches data the person asking should never see.
This is the biggest change since private LLMs became popular. With MCP, an agent can search Slack, read Google Drive files, query Salesforce or run SQL against Postgres and Snowflake. A request for a customer's email can return their SSN, card number and medical history too. All of it lands in the model's context, private or not. Traditional DLP that watches email and file transfers never sees this traffic.
Attackers can hide instructions inside a document, ticket or web page that an agent later reads. The agent follows them and sends data out through a tool it is allowed to use. In 2025, Invariant Labs showed a poisoned MCP server pulling a full WhatsApp message history this way. A private model does nothing to stop it. See MCP prompt injection and MCP rug pulls.
Even with a private LLM in place, employees still use public tools. They paste into ChatGPT, upload to Gemini, and install Claude Desktop. Developers spin up MCP servers on their laptops with direct database access. Security teams cannot protect tools they do not know about. See shadow AI and shadow MCP.
Regulators and auditors want to know what data an AI system touched, when and for whom. Most private LLM setups log requests, not the sensitive data inside them. Building that logging yourself takes real engineering time.
Running one private model takes GPUs, storage, patching and people. Most companies now run several, plus the public tools employees prefer. Each one is another place where sensitive data can end up, which is why the controls need to sit around the data, not around each model.
Strac works as a data firewall for AI. Instead of guarding one model, it sits at every point where data enters AI and applies one policy everywhere. It works the same whether your team uses a private LLM, a public tool, or both.
The Strac browser extension checks what employees type, paste and upload into AI tools before it is sent. It covers ChatGPT, Claude, Gemini, Copilot, Perplexity, DeepSeek and Mistral Le Chat, plus any SaaS app in the tab. It runs on Chrome, Edge and Firefox, and installs in minutes with no new browser to roll out. Read more in Gen AI DLP and the best browser DLP solutions for 2026.
More AI work now happens outside the browser. The Strac endpoint agent covers Claude Desktop, Claude Code and the ChatGPT desktop app on Mac, Windows and Linux. It can block, warn, allow or audit, and it reads text inside screenshots using OCR.
Strac MCP DLP sits between your AI agents and the systems they connect to. Every tool call passes through Strac, which checks the response and removes sensitive values before they reach the model. The agent still gets a useful answer. It just does not get the SSN or card number it never needed.
On every MCP tool call, Strac:
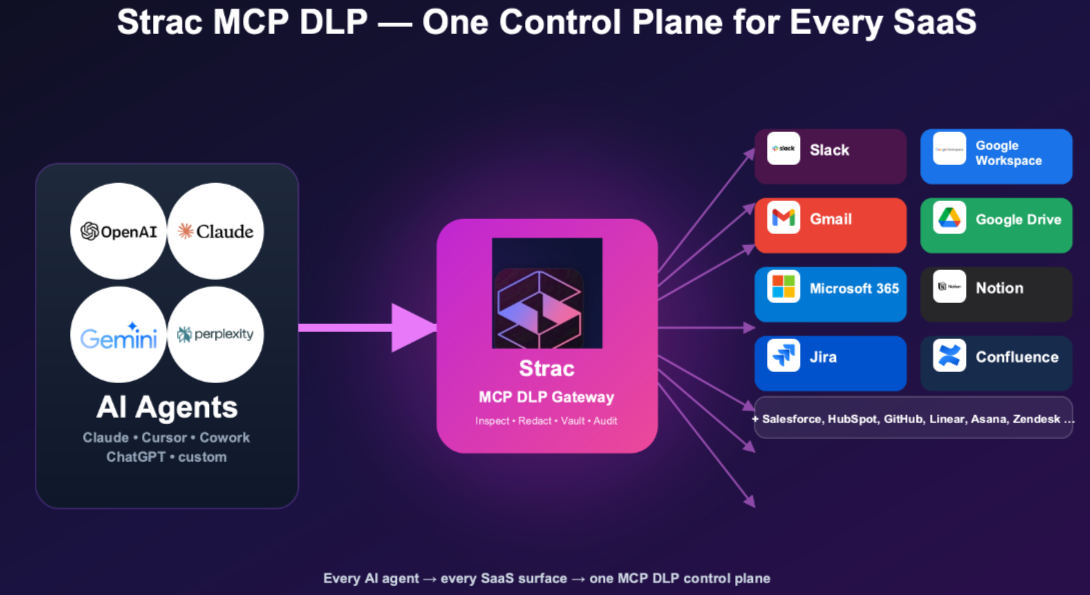
It works with every MCP-compatible client, including Claude (web, Desktop, Claude Code and Cowork), ChatGPT and Codex, Gemini CLI, Copilot Studio, GitHub Copilot, Perplexity, Cursor, Windsurf and Cline. Developers can also add Strac redaction to their own agents with the open-source strac-mcp-dlp server. For the controls around it, see the MCP gateway, MCP data security and agentic AI security.
Strac has setup guides for the MCP servers your agents are most likely to use:
Strac is a listed Anthropic Claude Compliance API partner. The Claude Compliance API integration gives security teams a second view of sensitive data moving through Claude Enterprise. Strac also has a dedicated ChatGPT DLP integration.
Agents can only leak what they can reach. Strac's data discovery and classification and DSPM scan the same apps your MCP servers connect to, so you know where sensitive data sits before an agent finds it. Data lineage shows where it moves next, and SaaS DLP cleans it up at the source in tools like Slack, Google Drive and Salesforce. Shadow AI discovery shows which AI tools and agents are in use that nobody approved.

Strac ships 100+ detectors. You can see the full list in the Strac catalog of sensitive data elements.
Strac also reads text inside images (JPEG, PNG, screenshots) and files (PDF, Word, Excel, ZIP). That matters for AI, because people upload screenshots and MCP file servers return whole documents.
When Strac finds something, it acts on it, not just alerts:
Read more about these options in DLP remediation and AI DLP.
The rules do not change because an AI agent made the request instead of a person. If an MCP server reads patient records, HIPAA applies. If card data lands in a prompt, PCI DSS applies. GDPR and CCPA cover any personal data a model processes, and SOC 2 and ISO 27001 expect controls on how data moves.
Strac helps in two ways. It keeps regulated data from reaching the model in the first place, which removes the "right to be forgotten" problem for that data. And it logs every detection and action across the browser, endpoint and MCP, which gives auditors one record of what each user and agent touched. Teams in healthcare and fintech can roll out new AI tools under the same policy instead of starting from zero each time.
You do not need to rebuild your network or replace your private LLM. Most teams follow these steps:
Most teams are enforcing across several AI tools within the first hour. You can see it live in the weekly MCP and Gen AI security webinar.
Private LLMs are a good start. They keep the model in your environment and give you control over the infrastructure. But in 2026, sensitive data reaches models through browsers, desktop apps and AI agents connected to your most sensitive systems. A private model does not see or stop any of that.
No. A private LLM controls where the model runs. It does not stop sensitive data from going into prompts, retrieval indexes or agent tool calls, and it cannot limit who sees what in the output. You still need Gen AI DLP and MCP DLP around it.
Not in practice. Removing one record usually means retraining or rebuilding the model. The workable approach is to redact or pseudonymize personal data before it ever reaches training data, retrieval or prompts.
MCP DLP applies data loss prevention to the calls AI agents make through the Model Context Protocol. It finds sensitive data in tool responses and redacts or blocks it before it enters the model's context, with a log of every call.
Yes. The browser extension covers their web apps. The endpoint agent covers Claude Desktop, Claude Code and ChatGPT desktop. MCP DLP covers their agents and connectors. Strac also integrates with the Claude Compliance API.
Strac checks MCP tool responses for hidden instructions before the agent acts on them, and it can block or alert on unusual data flows. See MCP prompt injection.
They overlap. AI guardrails is the broad term for keeping AI safe. A data firewall for AI is the part focused on sensitive data, and AI DLP is the detection and redaction engine underneath. Strac does all three for the data layer.
“Don’t just alert on problems, fix them.”
Scott Roberts, Chief Information Security Officer, UiPath





Customers include