What is Sensitive Data Discovery and Classification?
Sensitive data discovery and classification involve identifying critical or confidential data in an organization and categorizing it according to its level of sensitivity or regulatory requirements.
In today’s data-driven world, organizations handle an overwhelming volume of information. Whether structured in databases or unstructured in email conversations and cloud storage, data permeates every aspect of business operations. As a result, the ability to discover and classify this data becomes critical, not only for safeguarding sensitive information but also for ensuring compliance with stringent regulatory requirements like GDPR, HIPAA, and PCI DSS.
The journey to secure data starts with two foundational elements: Data Discovery and Data Classification. In this blog post, we'll explore why these two processes are indispensable for modern security architectures, and how tools like Strac provide best-in-class solutions to automate and optimize data protection.
Short answer: Sensitive data discovery finds where regulated data (PII, PHI, PCI card data, secrets) actually lives, and classification labels it by type and sensitivity. Strac does both across 60+ integrations spanning SaaS, cloud, databases, endpoints, browsers, and AI tools, then remediates in place by redacting, masking, blocking, encrypting, or revoking access, not just alerting.
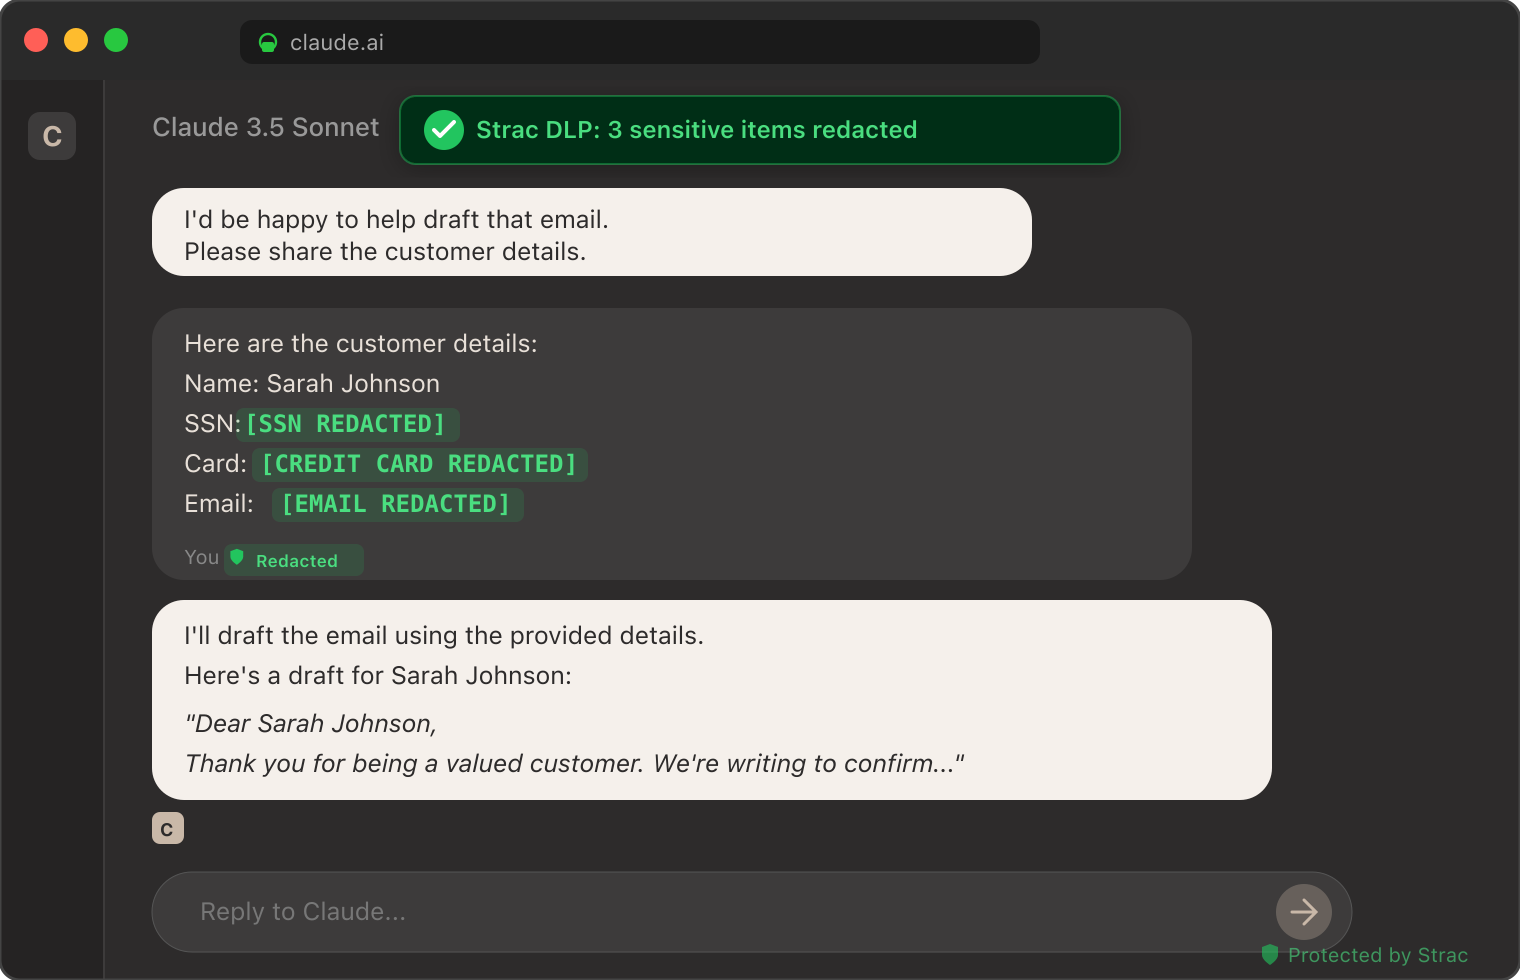
Strac does not just find sensitive data, it redacts it in real time.
✨ What is Data Discovery?
Data Discovery is the process of identifying where sensitive data resides across an organization's ecosystem. With data distributed across cloud platforms, SaaS applications, on-premise databases, and endpoints, gaining visibility into the data landscape is crucial for risk management and compliance.
Without a data discovery solution, organizations are effectively blind to the risks they carry. Sensitive data such as PII (Personally Identifiable Information), PHI (Protected Health Information), or PCI (Payment Card Information) can easily be exposed to unauthorized users if not carefully monitored.
Contextual Analysis: Simply matching patterns or regex isn’t enough. Advanced data classification tools analyze the context around the data to ensure accurate categorization. For example, keywords around PII or PHI help the system identify whether a piece of data is genuinely sensitive or a false positive.Custom Classification Policies: Every organization has unique compliance and security needs. Thus, data classification should allow for customizable policies that align with industry standards or internal security frameworks.Labeling for Protection: Once classified, sensitive data should be labeled appropriately to trigger security controls like access restrictions, encryption, and DLP policies. Data Discovery and Classification: Discover and Classify Sensitive Data across SaaS apps, Cloud apps, Endpoint devices with Strac
Automated Continuous Scanning: Modern data environments are dynamic, constantly ingesting new information. Therefore, a strong data discovery solution must provide continuous scanning capabilities, detecting sensitive data as it enters the system in real time.
Once data is discovered, it must be classified. Data Classification refers to the process of categorizing data based on its type and sensitivity. Classification allows organizations to implement appropriate security controls based on the risk associated with each data type. It also forms the foundation for data loss prevention (DLP), access control policies, and encryption strategies.
Key Features of Data Classification
Sensitive Data Identification: Data classification tools must be able to detect a wide variety of sensitive information, including PII (such as names, addresses, and social security numbers), PCI (credit card data), PHI, and intellectual property (e.g., source code, patents).
Data Discovery and Classification: Identify Sensitive Data with Strac
Contextual Analysis: Simply matching patterns or regex isn’t enough. Advanced data classification tools analyze the context around the data to ensure accurate categorization. For example, keywords around PII or PHI help the system identify whether a piece of data is genuinely sensitive or a false positive.
Custom Classification Policies: Every organization has unique compliance and security needs. Thus, data classification should allow for customizable policies that align with industry standards or internal security frameworks.
Labeling for Protection: Once classified, sensitive data should be labeled appropriately to trigger security controls like access restrictions, encryption, and DLP policies.
Why Data Discovery and Classification Matter
1. Regulatory Compliance
With laws such as GDPR, CCPA, and HIPAA imposing heavy fines for non-compliance, organizations are under immense pressure to protect customer data. Compliance mandates require organizations to have a clear understanding of what sensitive data they hold, where it is stored, and how it is protected. Failure to classify and secure sensitive data can result in data breaches, legal penalties, and significant reputational damage.
2. Risk Mitigation
Data breaches, either from internal misuse or external attacks, pose a significant financial and reputational risk. A comprehensive data discovery and classification strategy allows businesses to prioritize protection efforts on their most valuable assets, minimizing the risk of leaks or unauthorized access.
3. Cost Efficiency
Without proper data discovery and classification, security teams can easily waste time and resources chasing irrelevant or false security incidents. Accurate classification ensures that security controls, such as DLP, encryption, and access control policies, are only applied to sensitive data, reducing overhead and focusing efforts where they’re truly needed.
✨ How Strac Simplifies Data Discovery and Classification
Strac offers a fully integrated platform that automates the discovery and classification of sensitive data across SaaS applications, cloud environments, and endpoints. Here’s how Strac excels in each area:
1. Automated Discovery Across Platforms
Strac scans all corners of your data environment, from cloud databases like AWS S3 and PostgreSQL to unstructured sources like emails, cloud storage, and chat messages. Strac's automated discovery engine ensures you have real-time visibility into every piece of sensitive data across your organization.
With native integrations into platforms like Slack, Salesforce, Zendesk, and Google Drive, Strac delivers a unified approach to discovering sensitive data in both structured and unstructured formats.
2. Contextual Data Classification
Strac employs machine learning models and advanced pattern recognition algorithms to classify sensitive data based on both its format and context. Whether it’s detecting PII in a shared Slack message or discovering API keys in source code, Strac ensures that sensitive data is classified accurately to trigger the right level of protection.
For example, when a Google Drive file containing sensitive data is identified, Strac automatically tags it based on its classification and alerts administrators or automatically triggers remediation actions, such as restricting file sharing or encrypting the document.
3. Real-Time Alerts and Automated Remediation
After discovering and classifying sensitive data, Strac goes a step further by providing real-time alerts when sensitive data is mishandled or exposed. This might include someone sharing a public link to a file containing PHI on Google Drive or emailing PCI data without encryption.
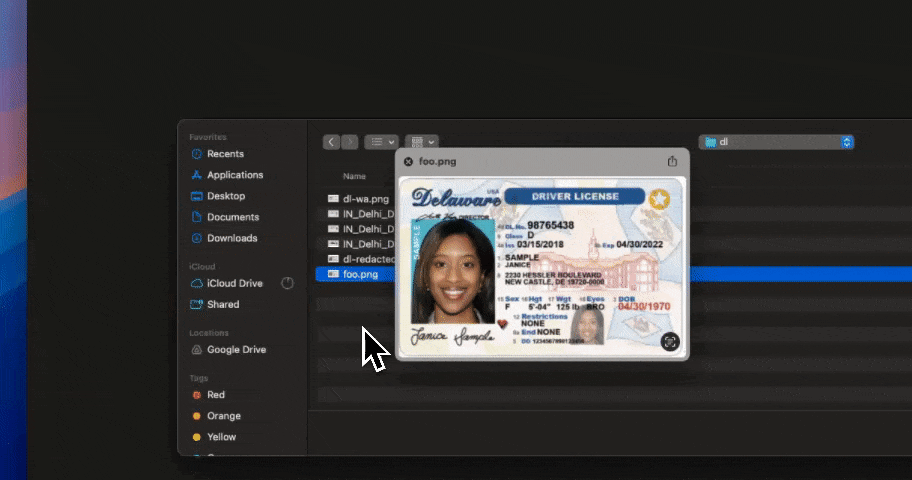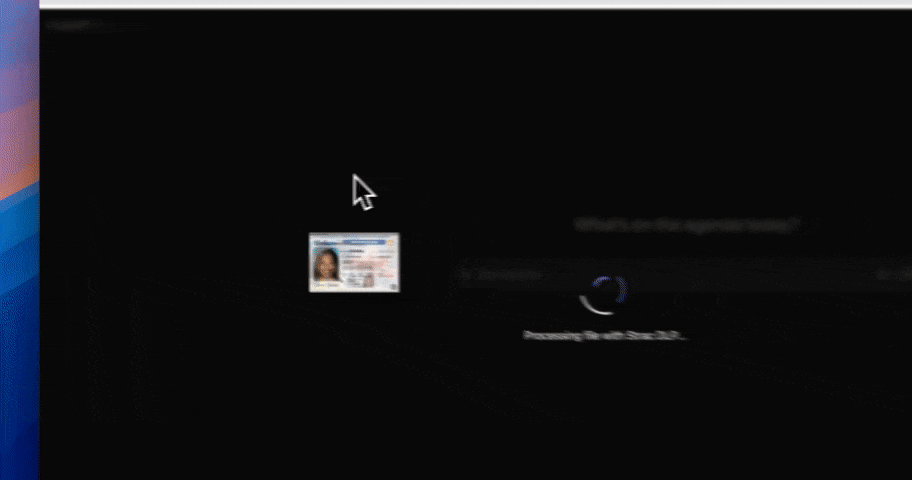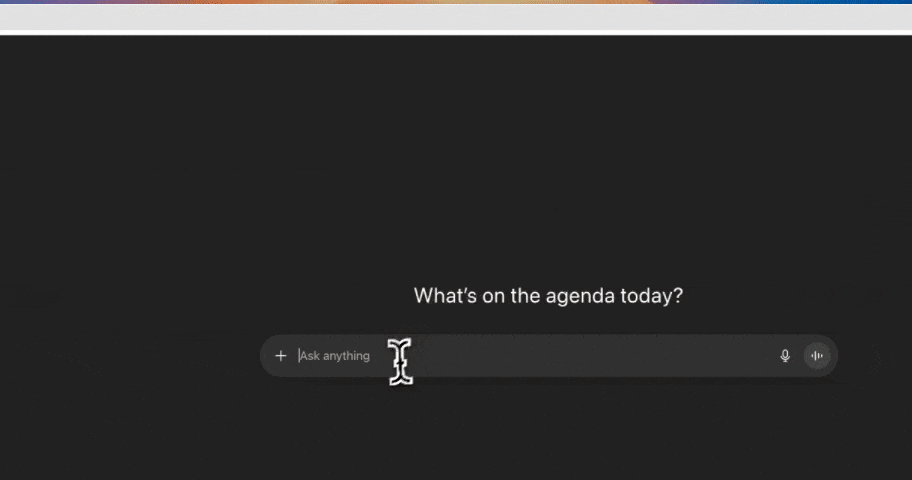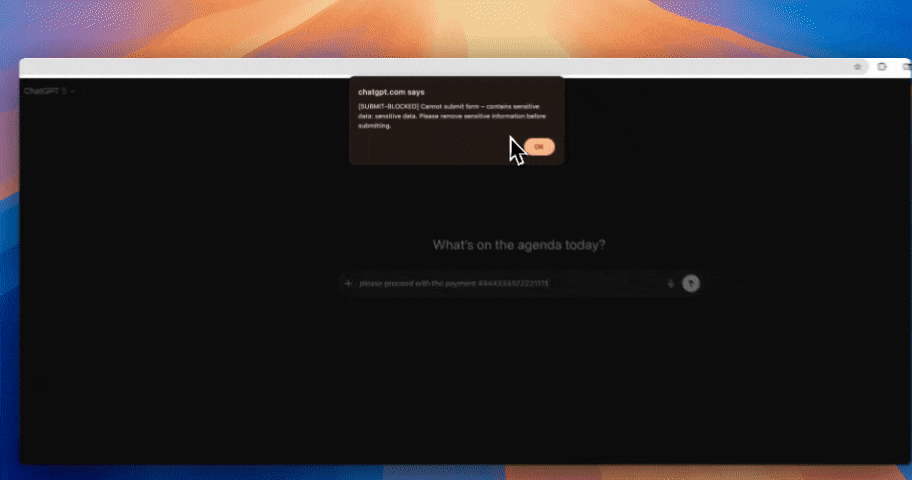
With automated remediation, Strac offers tools to mask, redact, block, or delete sensitive data, reducing the administrative burden on security teams and ensuring that data remains secure.
4. Customizable Data Classification Policies
Organizations can easily customize data classification policies within Strac, ensuring that they meet specific compliance requirements or internal security policies. For example, Strac enables organizations to define custom patterns for specific types of financial data or intellectual property, ensuring that nothing is overlooked.
Sensitive Data Discovery and Classification: Automatic Labeling and Remediation of Sensitive Files
5. Audit and Reporting
Strac maintains a comprehensive audit trail of all data discovery and classification actions, making it easier to generate compliance reports or respond to security incidents. This level of transparency is critical for demonstrating compliance during audits and ensuring that sensitive data is handled appropriately.
AI changed where sensitive data flows. Strac discovers and classifies the data going into AI DLP tools like ChatGPT, Claude, Gemini, and Copilot, and governs what MCP DLP agents can pull from your systems, redacting sensitive values in tool responses before the model ever sees them.
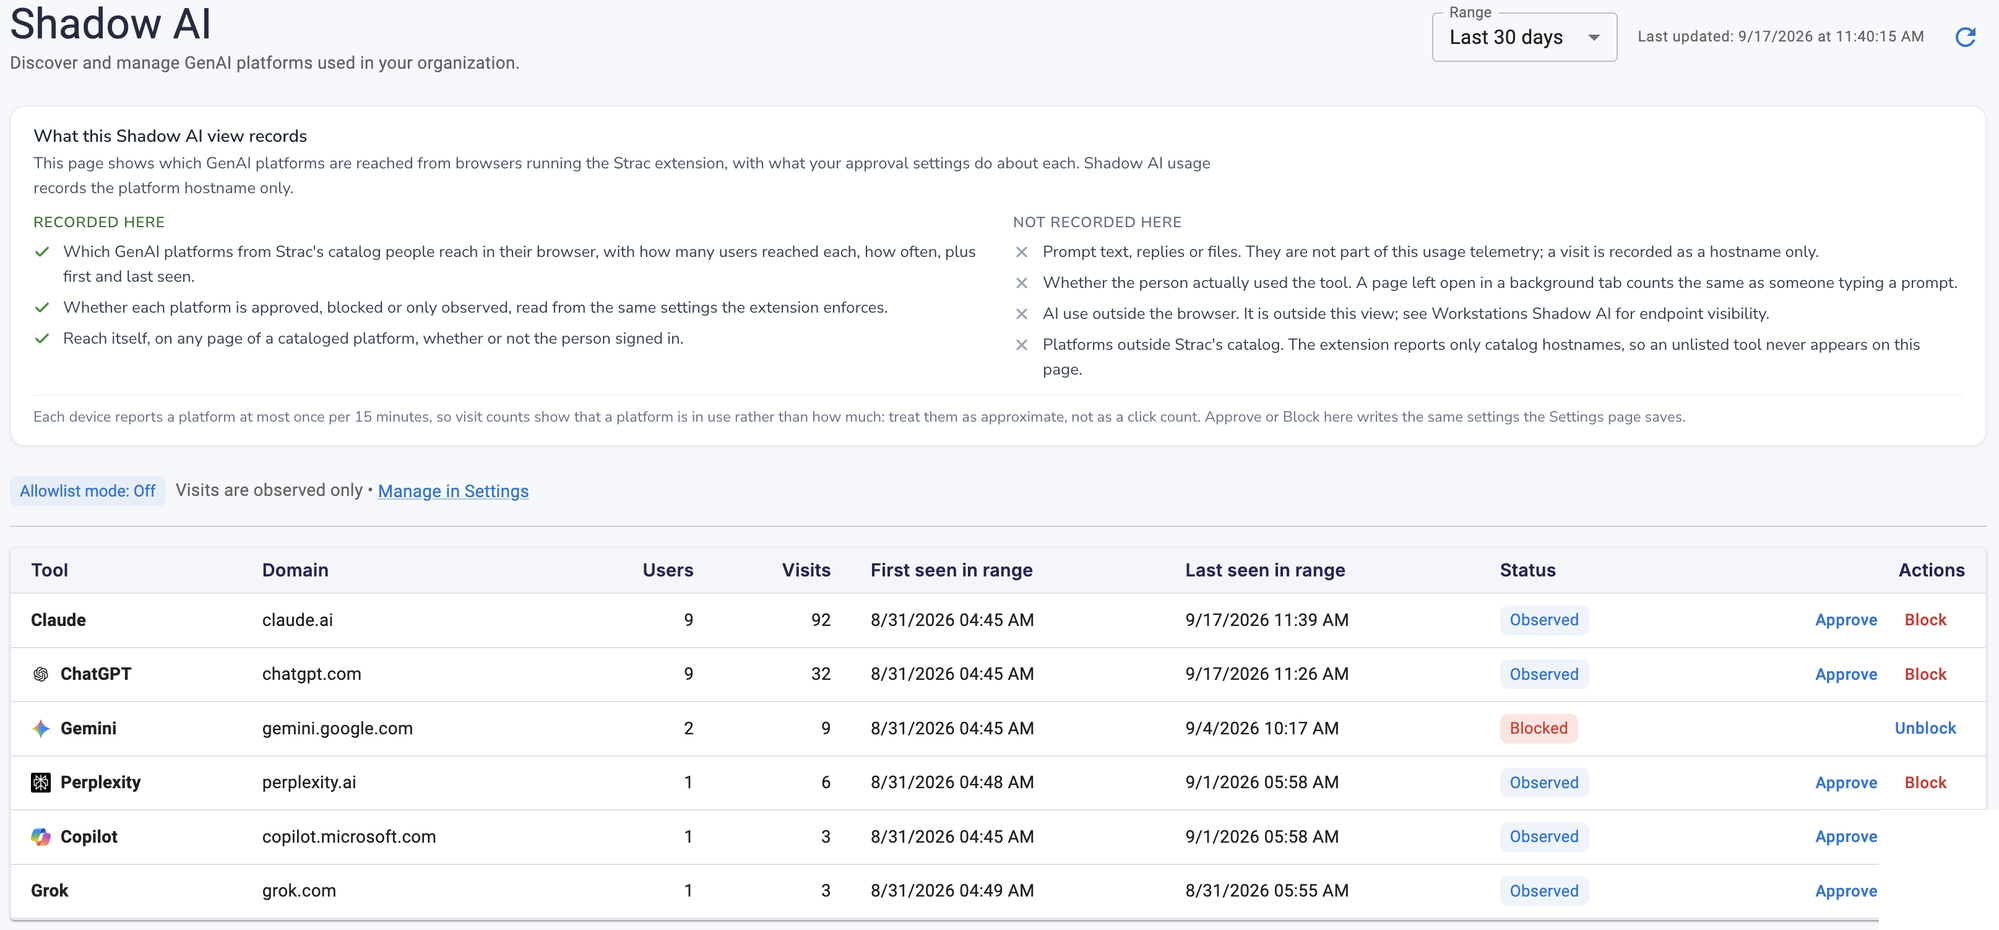
Strac also surfaces shadow AI, the unmanaged tools your data is flowing into.
It also surfaces shadow AI, the unsanctioned tools employees adopted, so discovery covers the AI surface, not just SaaS and cloud.
How Strac classifies data: 100+ detectors with ML and OCR
Strac ships 100+ built-in detectors for PII, PHI, PCI card data, secrets, and source code, and you can add a custom detector described in plain English. OCR and ML mean it also finds data inside images, screenshots, PDFs, and Office documents, not just plain text, so classification is accurate across every file type.
🌶️ Spicy FAQs: sensitive data discovery and classification
What is the difference between data discovery and classification?
Data discovery finds where sensitive data lives across your systems; classification labels each piece by type (PII, PHI, PCI, secrets) and sensitivity. You need both: discovery to know what you have, classification to decide how to protect it.
Where can Strac discover sensitive data?
Across 60+ integrations: SaaS apps (Slack, Google Workspace, Microsoft 365, Salesforce, Zendesk, Jira, Notion, Box, and more), cloud and databases (AWS, Azure, Snowflake, Postgres, Oracle), endpoints (Mac, Windows, Linux), browsers (Chrome, Edge, Firefox, Safari), and AI tools (ChatGPT, Claude, Gemini, Copilot, and MCP).
Does Strac just find data, or does it remediate it?
It remediates. After discovery, Strac redacts, masks, blocks, encrypts, deletes, or revokes sharing in place under your policy, keeping originals in an audited vault, rather than only flagging risk on a dashboard.
Is Strac data discovery agentless?
Yes. Strac connects to SaaS, cloud, and databases over APIs with no agents to deploy. Endpoint and browser coverage uses a lightweight agent and extension where in-scope.
Can Strac discover data inside images and PDFs?
Yes. Strac uses OCR and ML detectors, so it finds sensitive data inside images, screenshots, PDFs, and Office documents, not just plain text.
Conclusion: Elevate Your Data Security
Data discovery and classification are the pillars of a solid data security strategy. With sensitive information scattered across cloud applications, emails, endpoints, and databases, organizations need a robust platform to automatically discover, classify, and protect their data.
Strac provides a seamless, automated solution that handles every aspect of data discovery and classification, empowering security teams to stay ahead of risks and comply with regulations. By integrating with multiple platforms and offering real-time remediation, Strac stands out as the ultimate data security partner for organizations of any size.
Discover & Protect Data on SaaS, AI, MCP, Endpoints & Cloud
Strac provides end-to-end data loss prevention for all SaaS and Cloud apps. Integrate in under 10 minutes and experience the benefits of live DLP scanning, live redaction, and a fortified SaaS environment.