October 1, 2026

8
min read
Understanding the Data Loss Prevention Process
The data loss prevention process finds sensitive data, classifies it, enforces controls, and remediates exposure across SaaS, cloud, browser, GenAI, and MCP.
· The data loss prevention process is theoperating loop that discovers sensitive data, classifies it, enforces controlson every action that touches it, remediates exposure, and proves the outcome toauditors.
· The process is harder in 2026 because data nolonger moves through predictable channels: it moves through a browser pasteinto a chatbot, an agent call over Model Context Protocol, and a file sharedfrom a personal device, and each of those exfiltrates a customer record inabout one second.
· Legacy DLP was built for email and networkegress, so it inspects channels that no longer carry the risk and misses theones that do. Read more on whylegacy DLP fails for AI.
· Strac runs the full process on one platformacross SaaS, cloud, browser, endpoint, GenAI, and MCP, with automatedremediation instead of alert queues: endpoint DLP, SaaS, AI DLP, and MCP DLP.
· This is the operational layer beneath AI data governance. Start from that pillarfor the policy view, and use this post for the process itself.
The data loss prevention process is the continuous loop an organization runs to keep sensitive data from leaving its control. It has five stages: discover, classify, define policy, enforce, and remediate. Governance sits above it and audit evidence falls out of it.
The word that matters is process. DLP is not a product you switch on and leave alone. Data is created every hour, in new tools, by new people, and it moves through surfaces that did not exist in the last budget cycle. A process assumes that. A one-time deployment does not.
Two failure modes show up when teams treat DLP as a project rather than a loop:
Detection tells you sensitive data is exposed. Remediation is what stops the leak.
Classic DLP assumed sensitive data left the company through a small number of gates: an email attachment, an FTP transfer, a USB stick. Watch the gates and you covered the risk. That assumption is gone.
Sensitive data now leaves through paths that never touch a mail gateway:
The pattern across all five is the same: the risk moved from the transport layer to the data layer, and inspection has to move with it. Legacy tools inspect the channels that used to matter; the modern process inspects the content of every action, wherever it happens.
1. Discover. Find where sensitive data actually lives, not where the architecture diagram says it lives. That means SaaS apps, cloud buckets, data warehouses, endpoints, collaboration tools, and the AI tools employees adopted without asking. Discovery that skips shadow tooling produces a confident, wrong map.

👉 See how to detect shadow AI.
2. Classify. Label what you found by data type and sensitivity: PII, PHI, PCI, credentials and API keys, source code, and internal intellectual property. Accuracy here decides everything downstream, because a classifier with a high false-positive rate trains your team to ignore it.
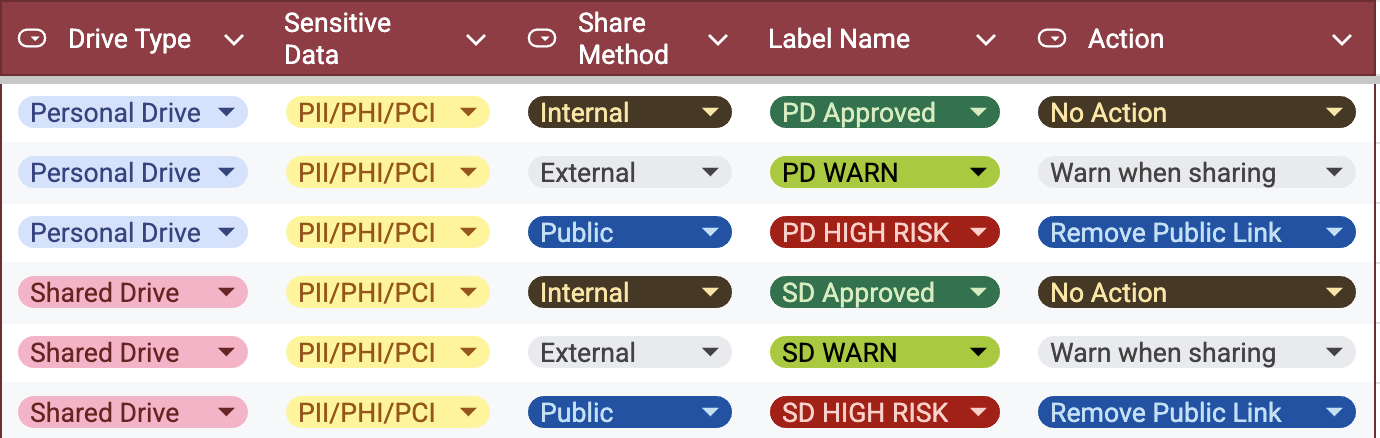
3. Define policy. Write rules in terms of data class, destination, and user context rather than file paths. A policy that says "no customer PII to unsanctioned generative AI destinations" survives a tool change; a policy that names one chatbot does not.
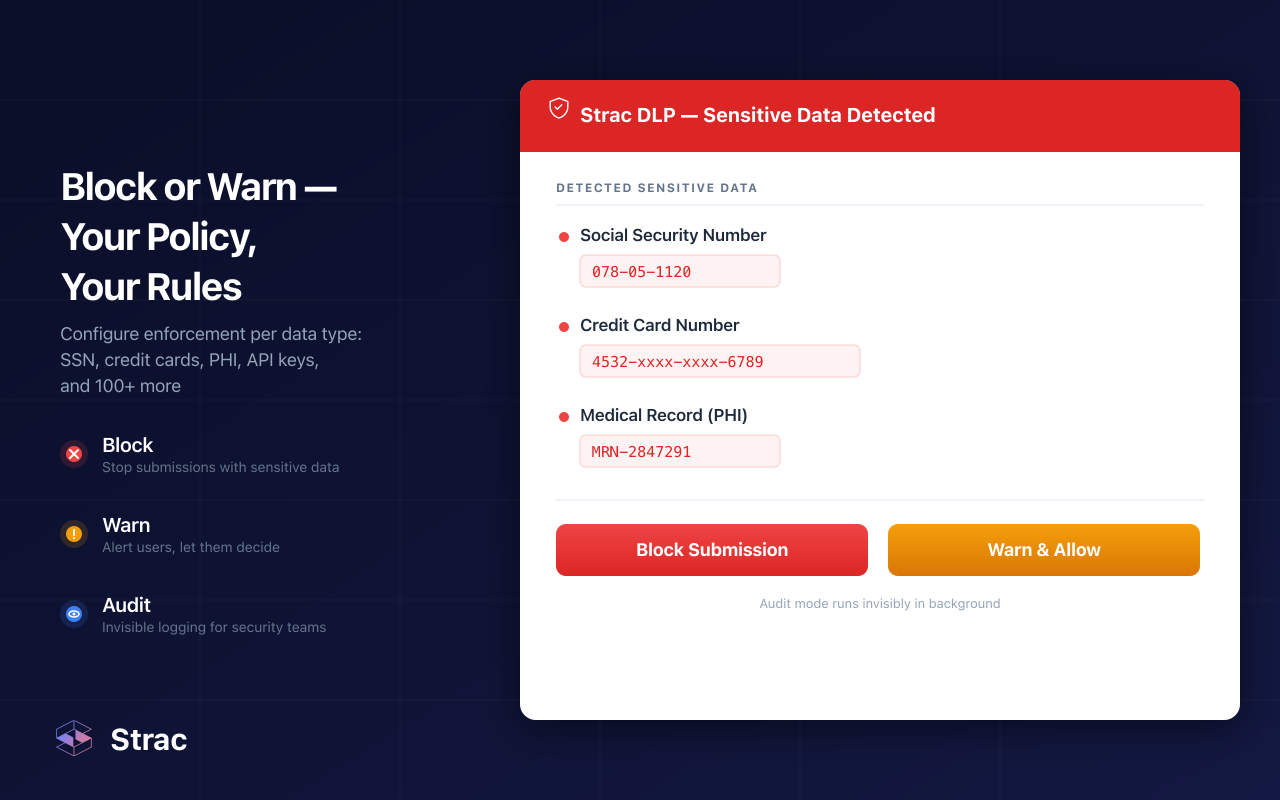
4. Enforce. Apply the policy inline, at the moment of action, on every surface: the paste, the upload, the share, the agent tool call, the API response. Enforcement after the fact is reporting, not prevention.
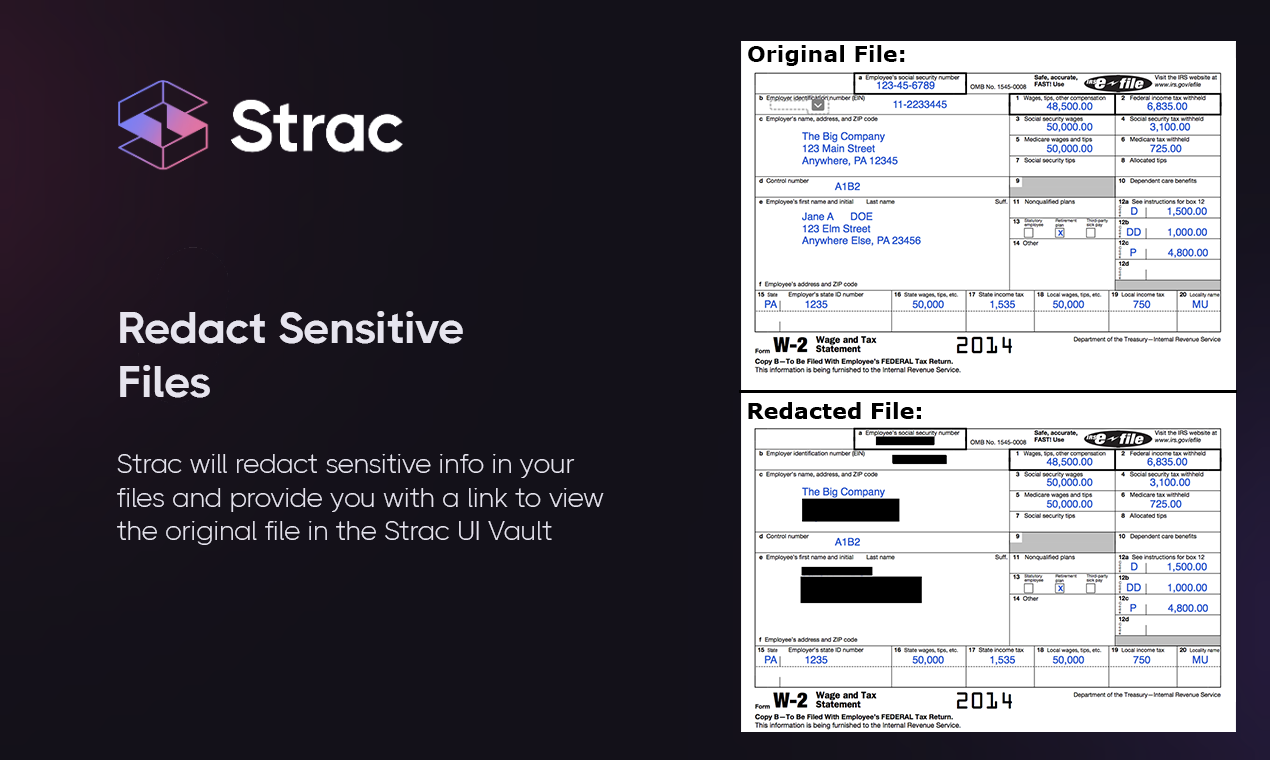
5. Remediate and prove. Redact, block, coach, or revoke, then keep the evidence. The same log that satisfies SOC 2, ISO 27001, HIPAA, PCI DSS, GDPR, and the EU AI Act is the log that tells you whether the process is working.
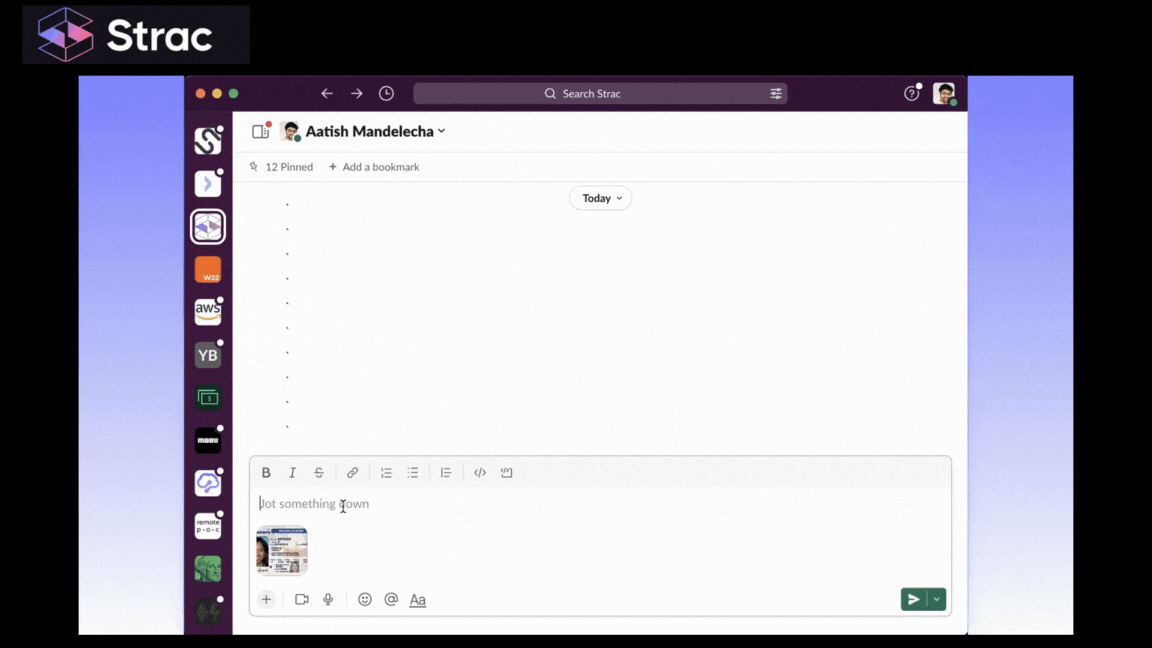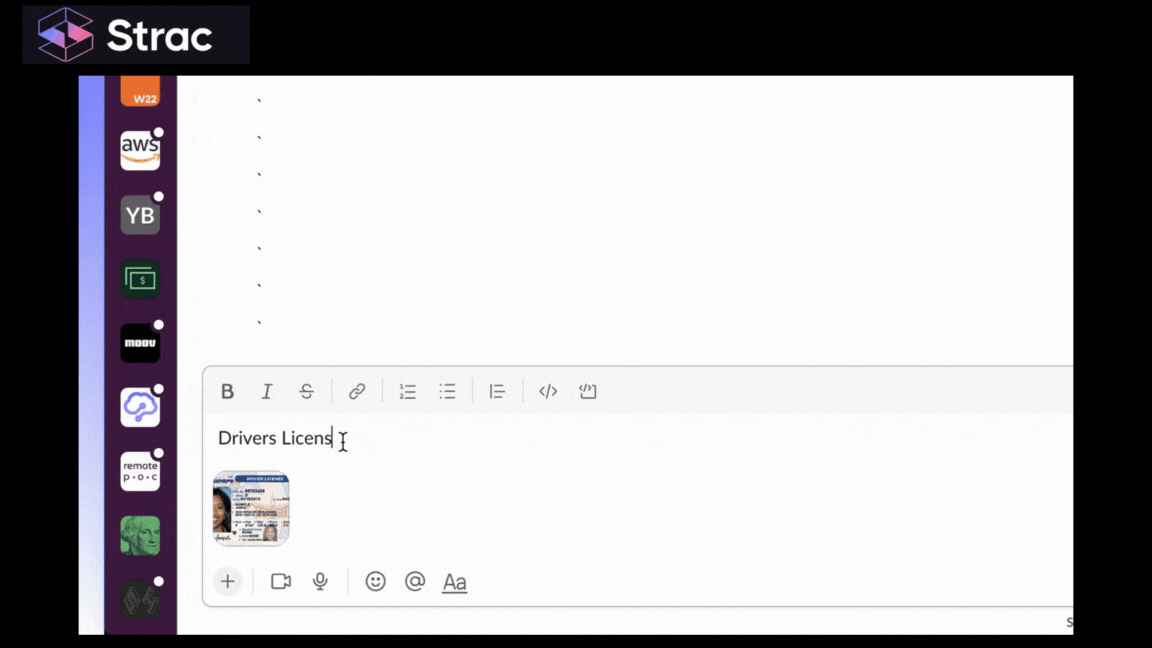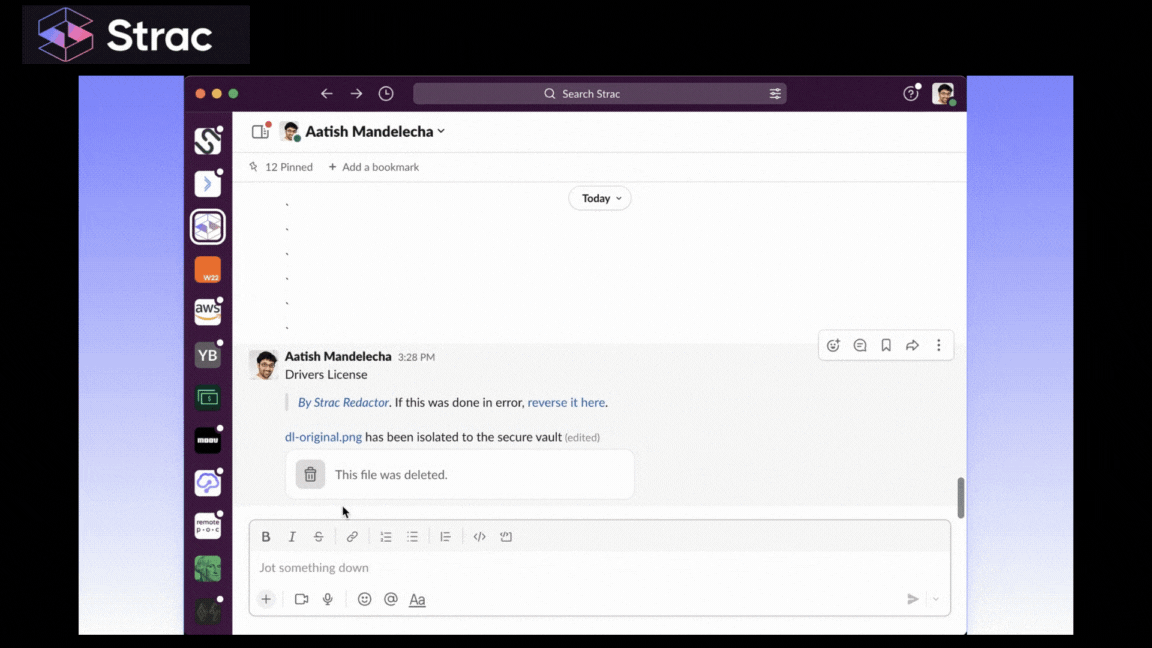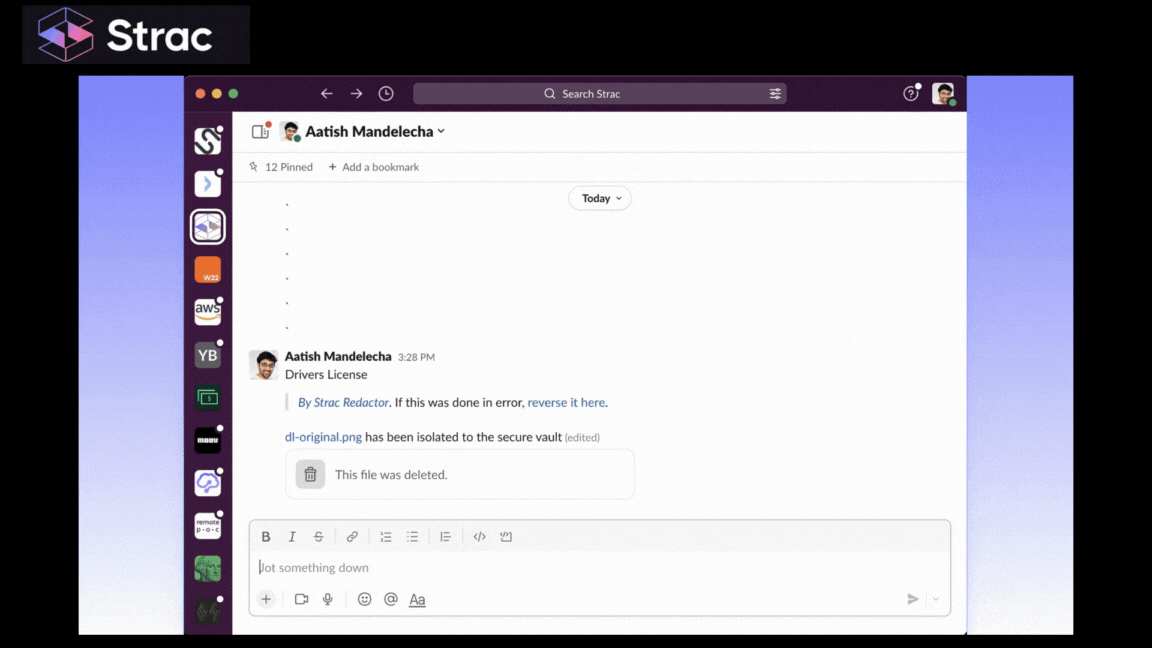
Each stage feeds the next, and the loop restarts continuously. Discovery is not a phase you complete; it is a job that runs.
A data loss prevention process is only as complete as the surfaces it covers. In 2026 that means all six:
Covering five of six is not a process with a gap. It is a process with an exit.
Remediation is where the process either pays for itself or does not. Four actions, in order of preference:
Strac detects and redacts sensitive data inline across every surface, so a policy violation resolves in the moment instead of joining a queue.
The ranking is deliberate. Blocking is the control everyone reaches for first and the one that gets disabled first, because it stops work. Redaction keeps the work moving and removes the data that made the action risky.
Most teams assemble the process from four vendors and spend the year making them agree with each other. Strac runs the whole loop on one platform:
One agent, one console: Strac shows which tools hold sensitive data, which actions moved it, and what was redacted.
Strac keeps no keystroke logs and no screenshots. The record is destinations and data classes, which is what a security team needs and what a privacy review will approve. A program that records content is a liability; one that records destinations and data classes is an asset.
Related reading: AI data governance, why legacy DLP fails for AI, shadow AI governance.
The data loss prevention process is not a deployment; it is a loop that runs for as long as the company creates data. Discover continuously, classify accurately, enforce inline on all six surfaces, and remediate automatically. Identity, network, and model controls all fail eventually, and when they do the data layer is the backstop: redact sensitive data on every action and a compromise never becomes a breach. Book a demo to see Strac run the full process across SaaS, cloud, browser, endpoint, GenAI, and MCP.
The tool enforces; the process decides what to enforce and proves it worked. A tool with no discovery loop protects a data map that expired months ago, which is why deployments that skip the process stall after the first quarter.
Because it inspects channels, not actions. Email and network DLP never see a browser paste into a chatbot or an agent response returned over MCP, so the two fastest exfiltration paths in 2026 fall entirely outside their coverage.
Yes, if redaction is the default action instead of blocking. Sensitive values are masked in place while the message, document, or agent response still does its job, so the work continues and the raw data never leaves.
No. A determined insider photographing a screen defeats every control on the market. That is the argument for the data layer: if sensitive values are redacted at the moment of every action, the data available to steal is already minimized.
It is the enforcement layer underneath it. Governance sets the policy and the accountability; the DLP process applies it to real data movement and produces the evidence. See AI data governance and shadow AI governance for the layer above.