September 22, 2026

7
min read
Improving DLP Accuracy: Reducing False Positives
DLP false positives waste analyst hours and get policies quietly turned off. What causes them in 2026, what they cost, and how context-aware detection fixes it.
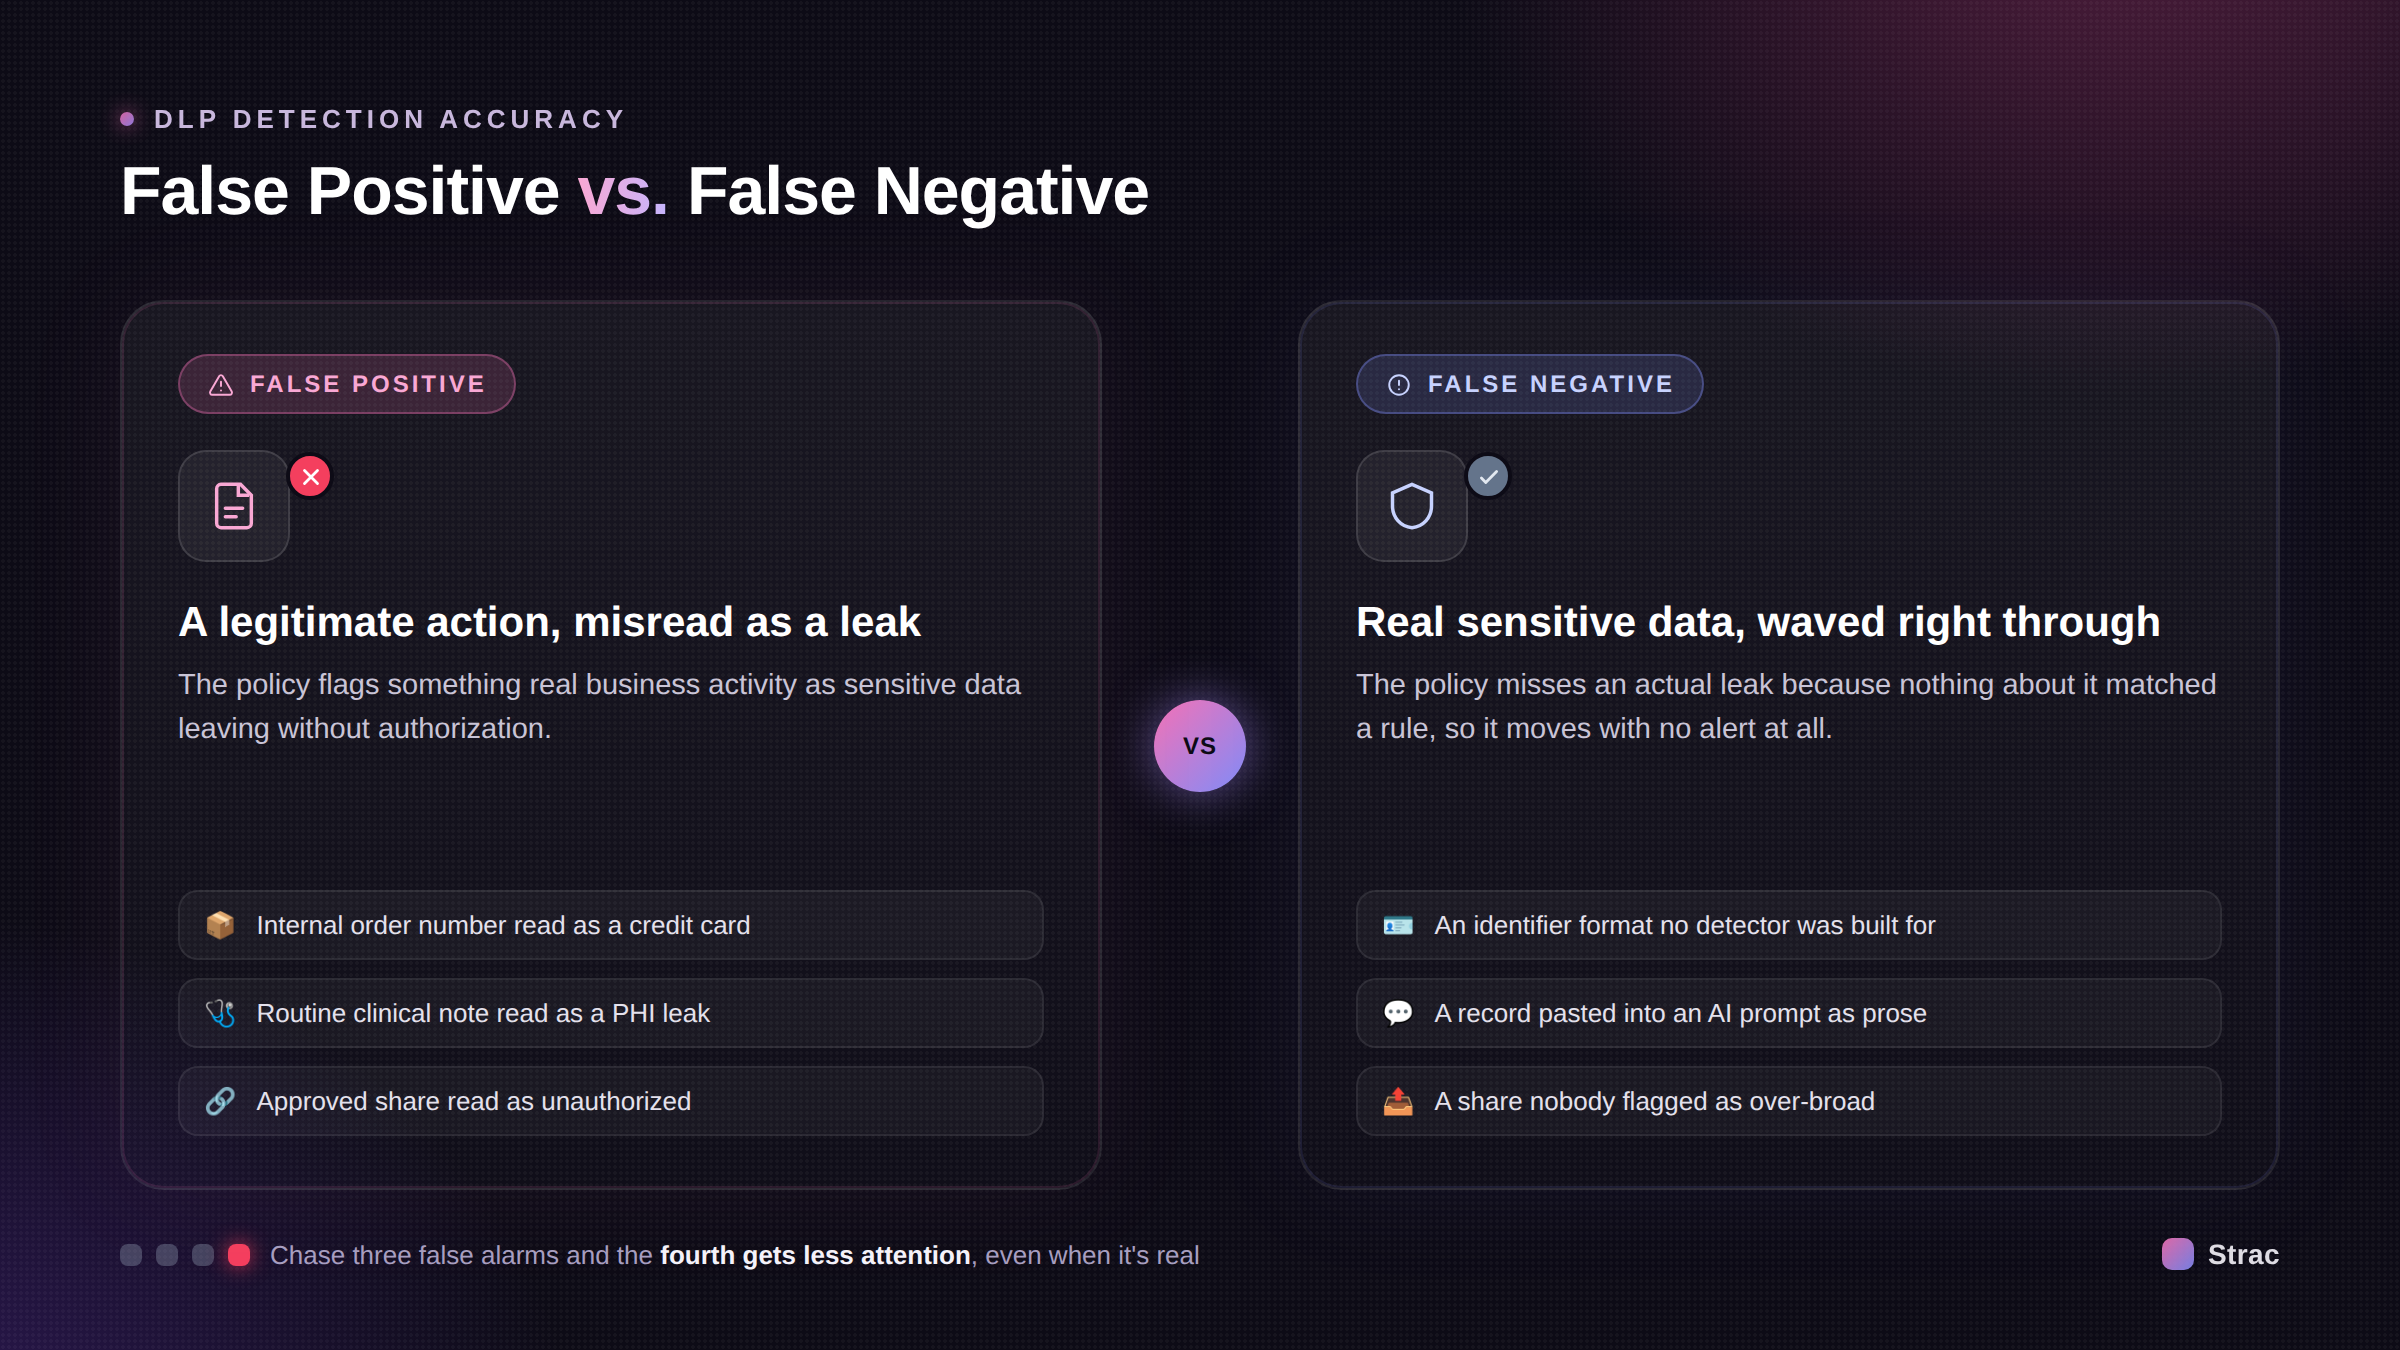
· A DLP false positive is a legitimate action thata policy flags as a data leak: an internal order number read as a credit card,a clinical term read as protected health information, an approved share read asan unauthorized one.
· Every new surface adds a new way to be wrong. Abrowser paste, a generative AI prompt, and an AI agent's MCP tool call eachcarry context a static rule cannot read, and an agent alone can generatethousands of calls an hour with no human reviewing any of them.
· Legacy DLP treats every pattern match as equallycertain, so teams either drown in a queue or quietly turn detection down untilthe control stops doing anything.
· Strac cuts the false positive rate withdetectors that use surrounding context and validation logic, not patternmatching alone, plus a feedback loop that keeps a confirmed false positive fromrepeating across SaaS, Browser, AI DLP and MCP DLP.
· Accuracyis the operational half of AI data governance.Start from that pillar for the full picture.
A DLP false positive is a legitimate action that a data loss prevention policy misclassifies as a data leak. An internal order number matches a credit card pattern. A routine clinical note trips a protected-health-information rule. An approved internal share gets caught by a policy written for the unapproved case.
The inverse is a false negative: real sensitive data that gets through undetected. Programs have to manage both, but false positives are the one that erodes a program first. An analyst who chases three false alarms in a row gives the fourth less attention, and the fourth one is sometimes real.
Static rules produced noise when sensitive data mostly lived in files and email, where a keyword or a regex pattern had a narrow, structured target. The noise compounds now that data moves through surfaces pattern matching was never built to read.
A browser tab carries a paste into a chat assistant, a draft in personal webmail, and a form on an unsanctioned SaaS tool, the kind of shadow AI usage no admin console shows, all inside the same few minutes, each with different context for what counts as risk. A generative AI prompt buries a customer name inside a paragraph of ordinary language, where a keyword match cannot tell a support agent quoting a ticket from an employee copying out a customer list. This is the specific failure covered in why legacy DLP fails for AI.
The newest source of noise has no human in the loop at all. An AI agent making tool calls over MCP, the kind of autonomous activity at the center of AI agent governance, can generate thousands of requests an hour, and a static rule scores every one of them the way it would score a single email, except nobody is reading the queue behind it. Detection tells a team a pattern matched. It does not tell them whether the match was a threat. Closing that gap is what MCP DLP and AI DLP exist to do.
A high false positive rate does not fail loudly. It fails by attrition. Each false alarm costs an analyst minutes to chase down, and a queue that floods trains the team behind it into alert fatigue: skimming rather than investigating. Legitimate work stalls while someone confirms a share was authorized. Trust in the tool erodes with every wrong call, and trust, once spent, does not come back because the next release shipped a better regex.
The predictable ending is that the policy gets loosened, or quietly switched from block to monitor-only, or the alerts get routed to a folder nobody opens. A DLP program that is technically switched on and a DLP program that is actually protecting data stop being the same thing, and the gap between them is exactly where a real leak gets missed.
Six patterns explain almost every false positive a program sees.
Custom detectors close most of that gap, because the data an organization most needs to protect is usually the data no vendor shipped a detector for. Validation logic, like checksums and proximity rules, does the rest by separating a real card number from an order ID that happens to be the same length. Both are part of automated data classification tools built on real sensitive data discovery and classification, and neither is optional if the false positive rate is going to move.
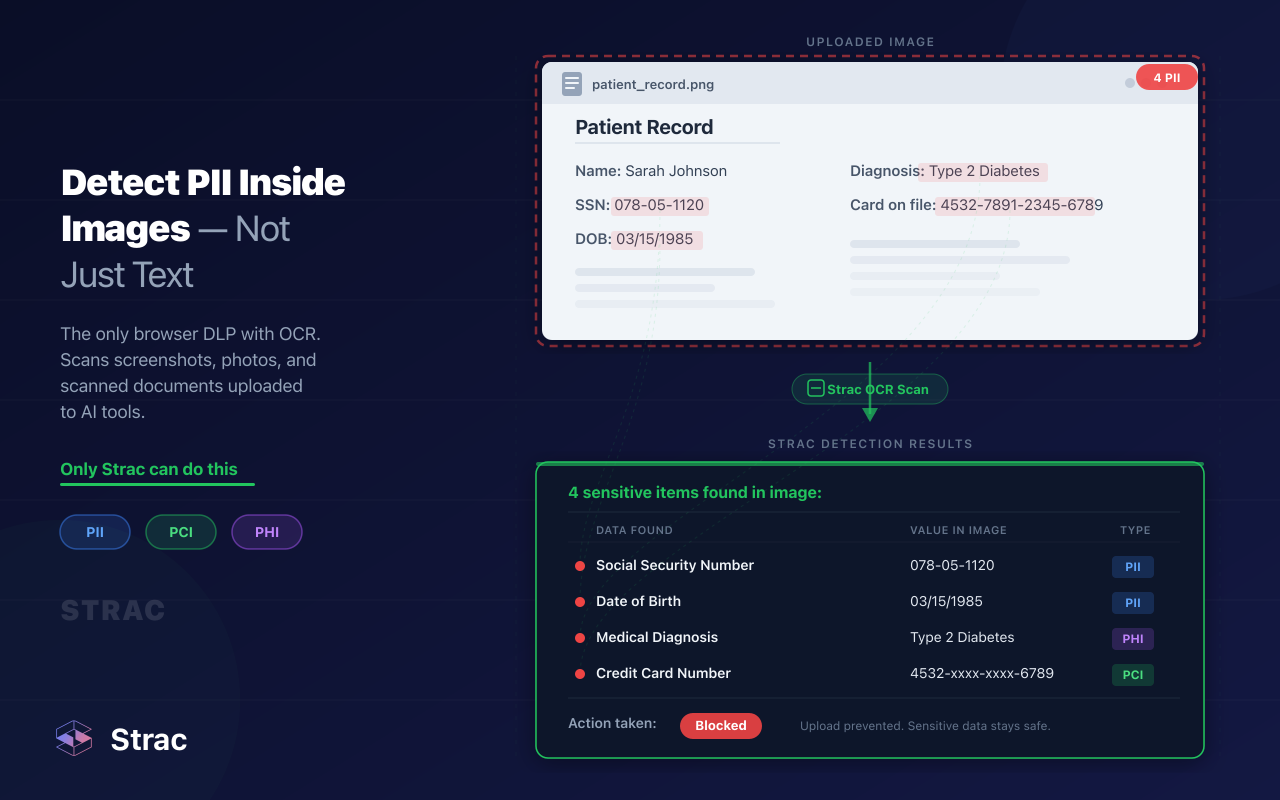
Watch Strac tell an internal order number apart from a real card number in a Slack message, hold a routine clinical term in a healthcare workflow, and catch the same customer record when it is pasted into a generative AI prompt.
Strac scores the surrounding context, not just the pattern. That is the difference between a queue an analyst trusts and one they learn to ignore.
Strac reduces the false positive rate with three things working together rather than a tighter rule.
Contextual detectors. Built-in detectors for PII, PHI, PCI data and secrets are backed by a published catalog of sensitive data elements, validation logic, and surrounding-context scoring, not a bare regex match. A PII scanner that only reads the pattern will always flag more than it should.
Custom detectors in minutes. An internal identifier format, a contract number, or a proprietary label can be defined once and applied everywhere SaaS DLP, endpoint DLP, AI DLP, MCP DLP and DSPM run, with no professional services engagement required.
A feedback loop that sticks. When an analyst marks a flagged item as a false positive, Strac records the context and stops repeating the same mistake in similar cases going forward, across every surface the policy touches. A false positive resolved once in Slack does not reappear the following week in a generative AI prompt or an MCP tool call.
None of this changes what happens when a match is real. Strac's remediation ladder still applies in order: redact or mask the sensitive value in place across Slack, email, tickets, docs, Google Workspace, SharePoint and Box; block the narrow set of destinations that can never be allowed; warn and coach the user at the moment of the action; and revoke access on a stale share or an over-broad grant that classification just flagged. Cutting the false positive rate is what makes teams willing to leave that ladder turned on. See data loss prevention compliance and the benefits of data loss prevention for how accurate detection changes incident response.
A DLP engineer who cannot answer the first line on this list is not tuning a program; they are guessing.
A DLP false positive is not a minor annoyance; it is the reason most programs quietly stop enforcing the policy they paid for. Detection tells a team a pattern matched. Accurate detection, built on context, validation logic and a feedback loop that actually sticks, tells them whether it mattered, across Slack, the browser, generative AI prompts and every MCP tool call an agent makes. Book a demo to see Strac cut false positives without cutting coverage.
👉 Related reading: AI DLP, MCP DLP, automated data classification tools, Slack DLP, Google Workspace DLP.
No. A false positive is a legitimate action wrongly flagged as a leak; a false negative is real sensitive data that gets through undetected. Programs need to track both, since a false positive rate driven to zero by loosening rules usually means the false negative rate just went up instead.
Most legacy tools rely on bare pattern matching with no validation logic or surrounding context, so anything shaped like a card number or a phone number gets flagged regardless of what it actually is. Adding custom detectors and context-aware scoring is what brings the rate down without losing coverage.
No, not if the fix is context and validation rather than a looser threshold. Strac tightens detection with contextual scoring and custom detectors, then remediates automatically through redaction, so accuracy improves and coverage does not shrink.
Not entirely. Free text is open-ended, and a person can describe a data element in a hundred ways no detector predicts. That is why the data layer matters as the backstop: even when a classifier misses or over-triggers, redaction limits what any single event can expose.
It is the share of flagged events that turn out to be legitimate, measured per policy so one noisy rule cannot hide inside an otherwise healthy aggregate number. See AI data governance for how detection accuracy fits the larger governance picture.