Everything to Know About Automated Data Classification in 2026
Automated data classification tools label sensitive data across SaaS, cloud, endpoint, browser and AI. In 2026 a label only counts if it triggers redaction.
· Automated data classification is the practice ofidentifying, categorizing and labeling data by sensitivity and context,continuously and without human filing, so that protective policy can be appliedto it.
· The job got harder in 2026 for one reason: datano longer sits still. It is generated in a browser, pasted into a model,retrieved by an agent over MCP, and written back to a SaaS app, all inside aminute.
· Most classification tooling stops at the label.It produces an inventory, a dashboard and a compliance report, and leaves theactual protection to a separate product that scans a different set of surfaceson a different schedule.
· Strac classifies and remediates in the samepass, across browser, endpoint, SaaS, cloud, GenAI and MCP, with redaction andmasking as the default action instead of a block.
· This is the discovery half of AI data governance.Start from that pillar if you are building the wider program.
What Are Automated Data Classification Tools?
Automated data classification tools are systems that inspect data at rest and in motion, decide what it is, and attach a durable sensitivity label to it without a human being asked to judge each file.
They work on two signals. Content is what is literally in the object: a 16 digit string that passes a Luhn check, a passport image, a private key, a patient identifier. Context is everything around it: who owns the file, which app it lives in, who it is shared with, what a user is about to do with it. Content alone produces noise. Context alone produces guesses. Good tools weigh both.
The output is not a report. The output is a decision that some other control can consume: encrypt, mask, restrict sharing, warn the user, revoke a link, or let it pass. A classification program that ends in a spreadsheet has done half a job.
Strac treats classification as the first stage of a single pipeline that runs through to remediation. If you are still comparing products, the market survey lives in the guide to data classification software.
✨ Why Classification Broke Between 2024 and 2026
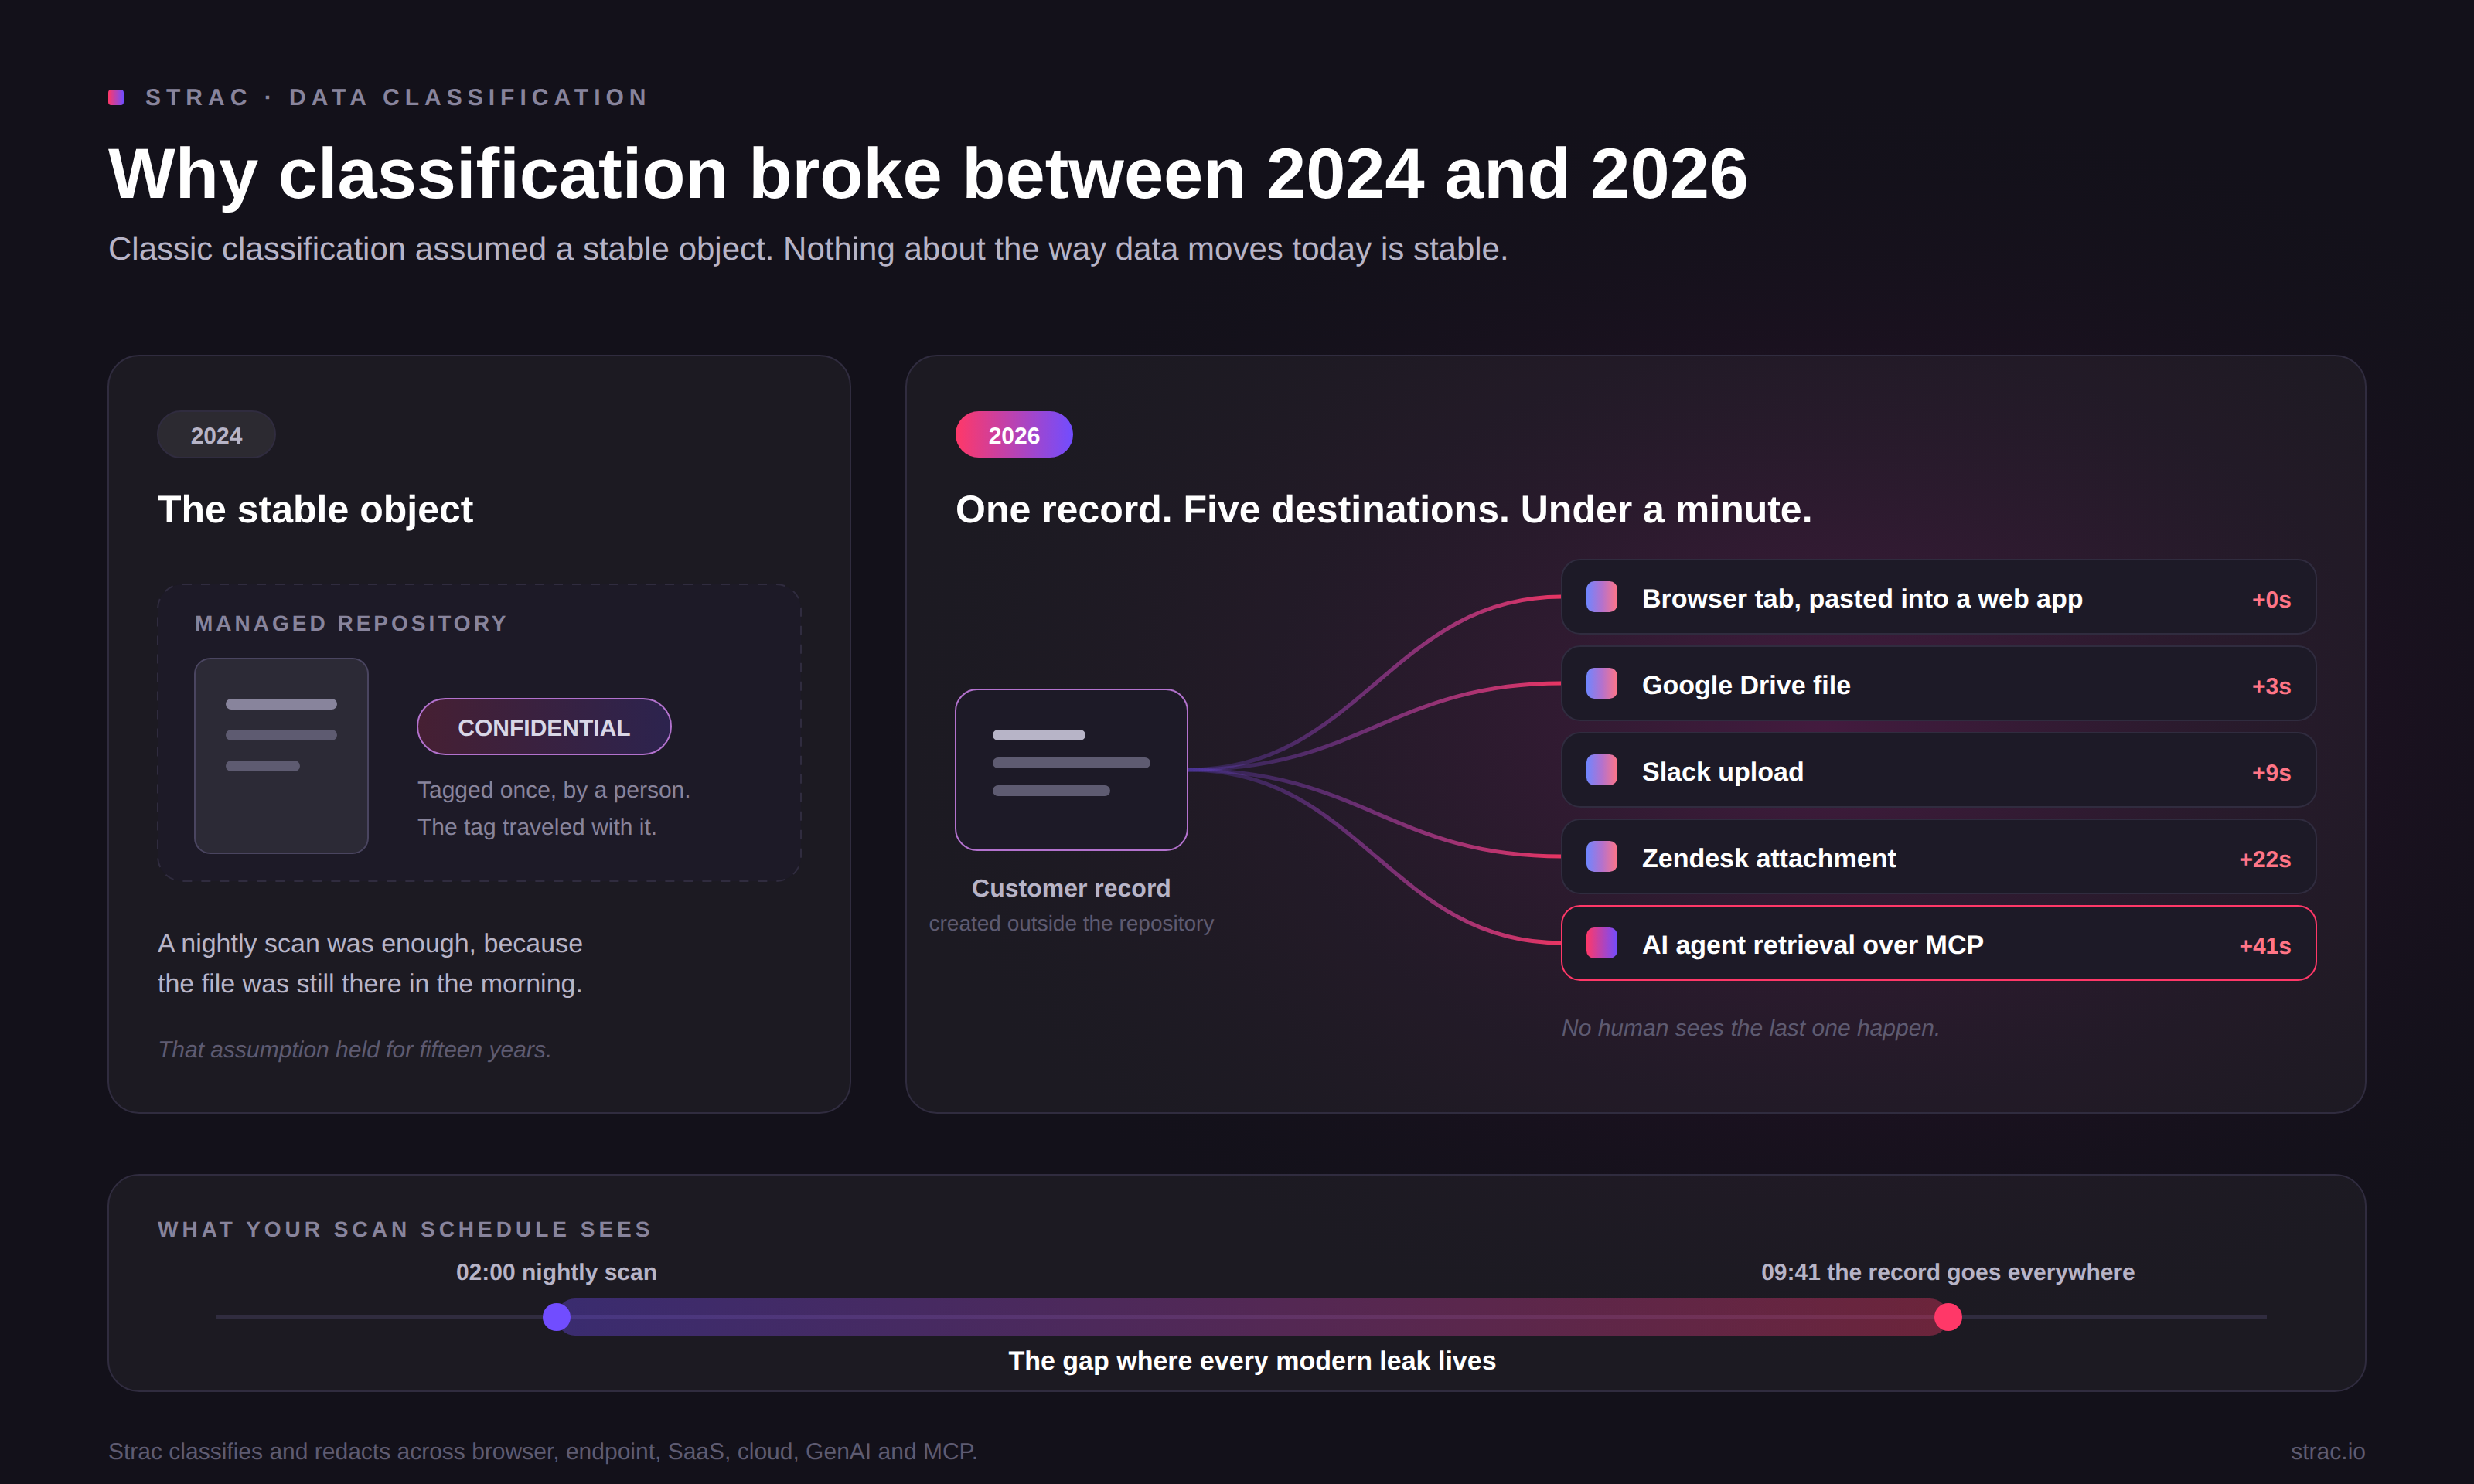
Classic classification assumed a stable object. A document lived in a repository, someone tagged it, and the tag traveled with it. That assumption held for about fifteen years and then stopped holding.
Three things changed at once. Sensitive data is now created outside managed repositories, in browser tabs, chat threads and support tickets. Copies multiply faster than any crawl schedule, because a Google Drive file becomes a Slack upload becomes a Zendesk attachment in seconds, and no Google Workspace DLP scan schedule keeps up with that. And a growing share of data movement is initiated by software rather than people, by AI agents retrieving records over MCP on behalf of a user who never sees them.
A nightly scan cannot see any of that. It sees yesterday. The gap between when data becomes sensitive and when your tooling notices is where every modern leak lives.
There is a second failure mode that gets less attention. Legacy pattern matching was tuned for structured formats and breaks on the unstructured, conversational data that now carries the most risk: a prompt, a chat message, a screenshot pasted into a ticket. The reasons are covered in detail in why legacy DLP fails for AI.
✨ How Automated Classification Actually Works
Four stages, in order. Every credible tool does all four, and the weak ones are weak at the same stage.
Discovery. Connect to every store and surface and enumerate what exists: cloud buckets, SaaS apps, endpoints, databases, shared drives, and the AI tools people actually use. You cannot classify what you have not found, which is why discovery coverage matters more than detector count. Strac's coverage is listed under DSPM integrations.
Detection. Inspect the content. This is regex and checksums for structured identifiers, machine learning classifiers for documents and free text, and optical character recognition for images, screenshots and scanned PDFs. Anything that cannot read an image is blind to a large and growing share of real sensitive data.
Contextual scoring. Combine the detection with ownership, sharing state, destination and user behavior to decide severity. The same social security number is a low priority inside an HR system and a high priority in a public Slack channel.
Labeling and handoff. Write the classification somewhere durable and hand it to a control that can act. This is the stage most programs skip, and skipping it is why so many organizations have an excellent inventory of data they are not protecting.
A data discovery platform that stops after stage three is a reporting tool. Useful, but not a control.
✨ Accuracy Is the Whole Product
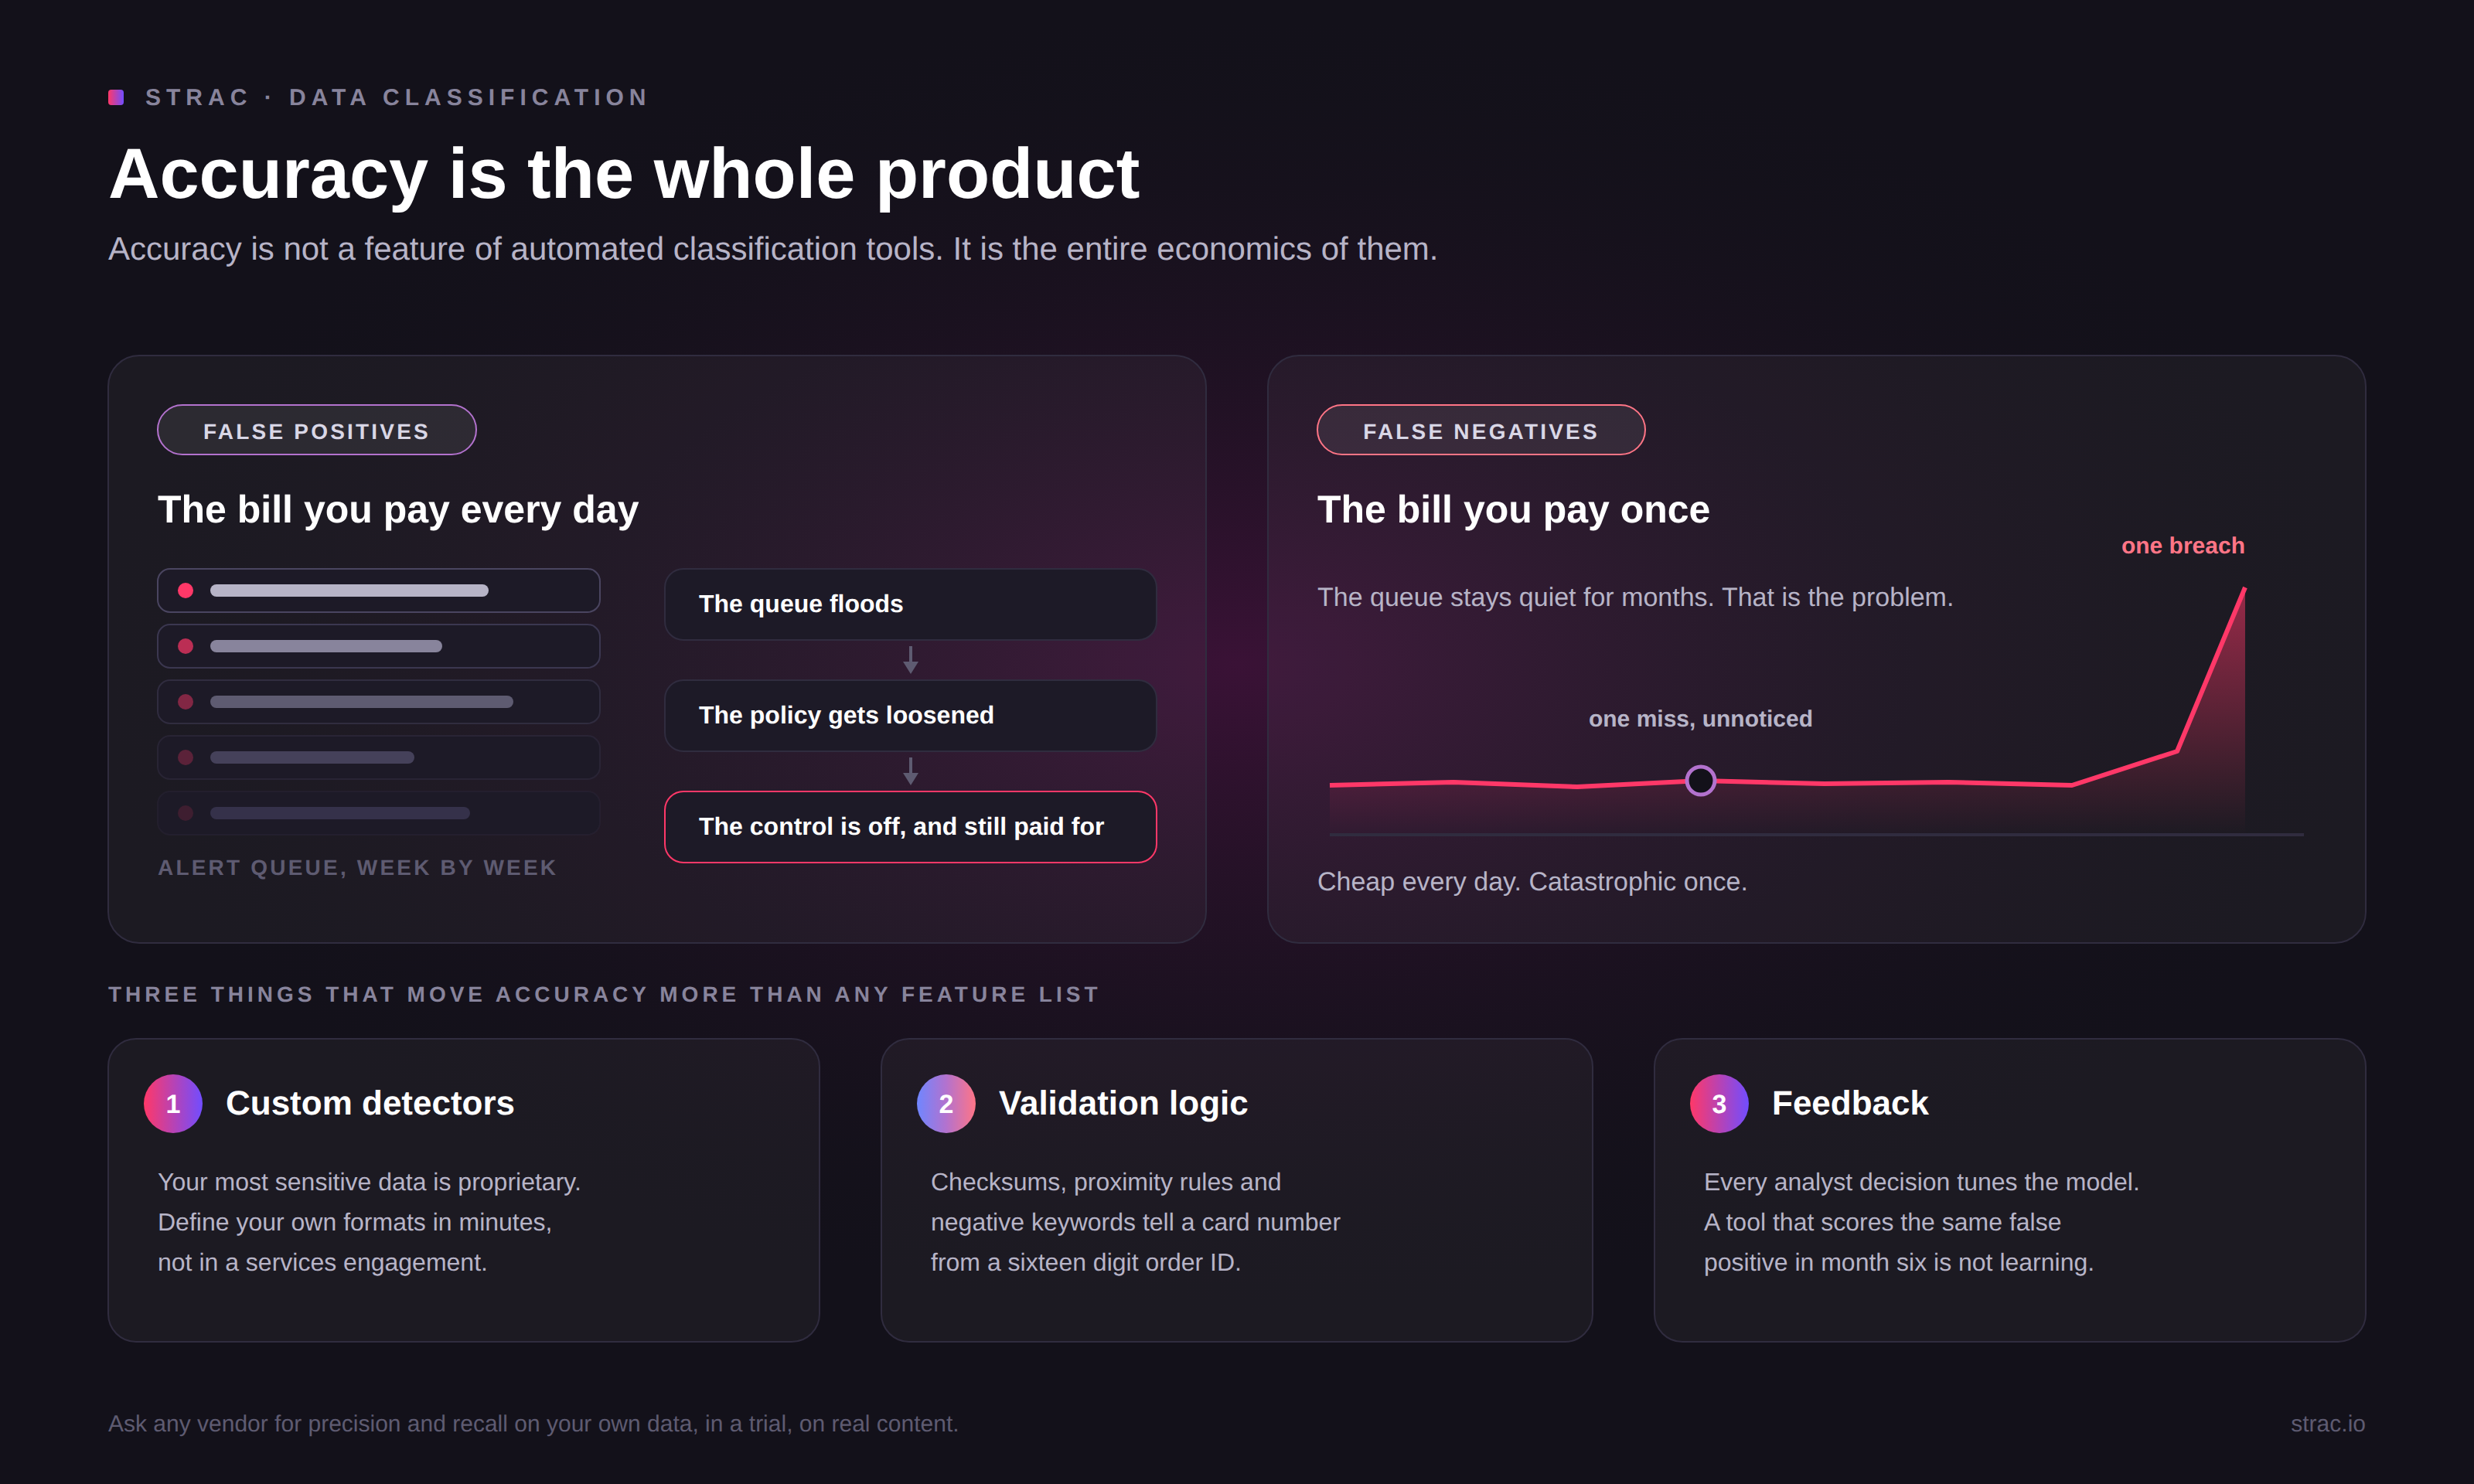
Accuracy is not a feature of automated classification tools. It is the entire economics of them.
False positives are expensive in a way that vendors rarely quantify. Each one costs analyst minutes, and a tool that floods a queue trains a team to ignore it. Within a quarter the policy gets loosened, the alerts get routed to a folder nobody opens, and you are paying for a control you have functionally turned off. False negatives are cheaper day to day and catastrophic once.
Three things move accuracy more than anything on a feature list:
Custom detectors. Your most sensitive data is usually proprietary: an internal account number format, a contract identifier, a schema field. Built-in detectors will never know about it, so the tool has to let you define your own in minutes rather than through a professional services engagement.
Validation logic. Checksums, proximity rules and negative keywords separate a real card number from an order ID that happens to be sixteen digits long.
Feedback. Every analyst decision should tune the model. A tool that scores the same false positive the same way in month six is not learning.
Ask any vendor for precision and recall on your own data, in a trial, on real content. A benchmark run on synthetic samples tells you nothing about your environment.
From Label to Action
Here is the sentence the rest of this post exists to deliver. Classification tells you what the data is; remediation is what keeps it from leaving.
The bridge between them is a small, fixed set of actions, and mature programs use them in this order:
Redact or mask. Replace the sensitive values in place and leave the rest of the object usable. This is the default, because it protects the data without taking the workflow away. It applies to Slack messages, email bodies, support tickets, documents, Google Drive, SharePoint and Box.
Block. Stop the action entirely. Reserved for the narrow set of cases where no redacted version is acceptable, such as a secrets file heading to an unmanaged destination.
Warn and coach. Tell the user what they are about to do and why it is risky, at the moment they do it. This is the control that changes behavior rather than just stopping it.
Revoke access. Pull back a public link, an over broad share, or a stale external collaborator on an object that classification just flagged.
Strac classifies and redacts sensitive data in the same pass, at the moment of the action, so a misdirected paste never becomes a disclosure.
✨ Strac: Classification and Remediation on One Platform
Strac is a Data Loss Prevention (DLP), Data Discovery and DSPM platform. Classification runs across every surface where data now moves, and every classification can trigger a remediation without a second product in the path.
SaaS. Continuous scanning of Slack, Google Workspace, Microsoft 365, Zendesk, Jira, Salesforce, Box, Dropbox and more, with redaction applied in the app itself. See SaaS DLP.
Endpoint. Classification on macOS, Windows and Linux devices, covering local files, USB transfers and print. See endpoint DLP.
Browser. Inspection of what users paste, type and upload into web applications, including the GenAI tools that never went through procurement. This is how you find shadow AI before it becomes an incident.
GenAI. Prompt level classification and redaction for ChatGPT, Claude, Gemini and Copilot, so employees keep the tool and the company keeps the data. See AI DLP.
MCP. Inspection of the data agents retrieve and send over Model Context Protocol, redacted on every action. See MCP DLP.
Cloud. Discovery and classification across S3, Azure Blob, Google Cloud Storage and managed databases, with posture findings surfaced alongside the data itself.
Detection combines built-in detectors for PII, PHI, PCI and secrets with custom detectors you define, and OCR so that a driver's license photo in a support ticket is classified the same way as a text field.
One agent, one policy: Strac shows where sensitive data lives, where it is heading, and redacts it on the way.
The 90-Day Rollout
Days 0 to 30, discover. Connect the top five data stores and the browser. Run classification in monitor only mode. Do not write a single policy yet. The goal is an honest map of where sensitive data actually is, which is never where the architecture diagram says.
Days 30 to 60, protect. Turn on redaction for the two highest volume, lowest ambiguity classes, usually payment data and government identifiers, in the two surfaces where they move most. Add custom detectors for your proprietary formats. Tune until the false positive rate is something an analyst can live with.
Days 60 to 90, prove and scale. Extend to GenAI and MCP, wire the findings into your reporting for SOC 2, ISO 27001, HIPAA, PCI DSS and GDPR, and publish two numbers to leadership: percentage of sensitive data under an active policy, and mean time from detection to remediation.
The Buyer Checklist
☐ Does it classify in real time at the moment of action, not only on a scan schedule?
☐ Does it read images and scanned documents, not only text?
☐ Can your team create a custom detector without vendor services?
☐ Does a classification trigger a remediation in the same platform?
☐ Does it cover the browser, GenAI and MCP, not only stores at rest?
☐ Can you see precision and recall on your own data during a trial?
The Bottom Line
Automated data classification tools earn their budget at the moment a label changes what happens next. Everything before that is inventory.
Identity controls, model guardrails and network policy all fail eventually. The data layer is the backstop: classify the sensitive value, redact it on every action, and a compromise never becomes a breach. Strac runs that loop across browser, endpoint, SaaS, cloud, GenAI and MCP, on one platform, with one policy.
Book a demo to see Strac classify and redact your sensitive data in your own environment.
🌶️ Spicy FAQs on Automated Data Classification Tools
Is automated data classification the same as data discovery?
No. Discovery finds where data lives; classification decides what that data is and how sensitive it is. Discovery without classification produces a map with no legend, which is why serious DSPM platform deployments do both.
Why doesn't our existing DLP classify AI and browser activity?
Because it was built for files and email gateways, and a prompt is neither. Legacy tooling inspects objects at rest or in transit over known protocols, while the riskiest movement in 2026 is a paste into a browser tab or an agent call over MCP.
Can we automate classification without blocking people's work?
Yes, and blocking is usually the wrong lever. Strac's default remediation is redaction, so the message still sends and the ticket still resolves, with the sensitive values removed. Users keep the tool, the company keeps the data.
Can automated classification ever be one hundred percent accurate?
No. Unstructured language is ambiguous, and any vendor promising perfect precision is describing a demo, not a deployment. That is exactly why the label has to drive an action: a program that redacts on a high confidence match contains the damage even when a borderline case is scored wrong.
Where does classification fit into overall AI governance?
It is the foundation. You cannot govern what a model or an agent touches until you know what the data is, which is why every control in AI data governance starts here.
Discover & Protect Data on SaaS, AI, MCP, Endpoints & Cloud
Strac provides end-to-end data loss prevention for all SaaS and Cloud apps. Integrate in under 10 minutes and experience the benefits of live DLP scanning, live redaction, and a fortified SaaS environment.